5 steps to automate operational workflows using Power Platform
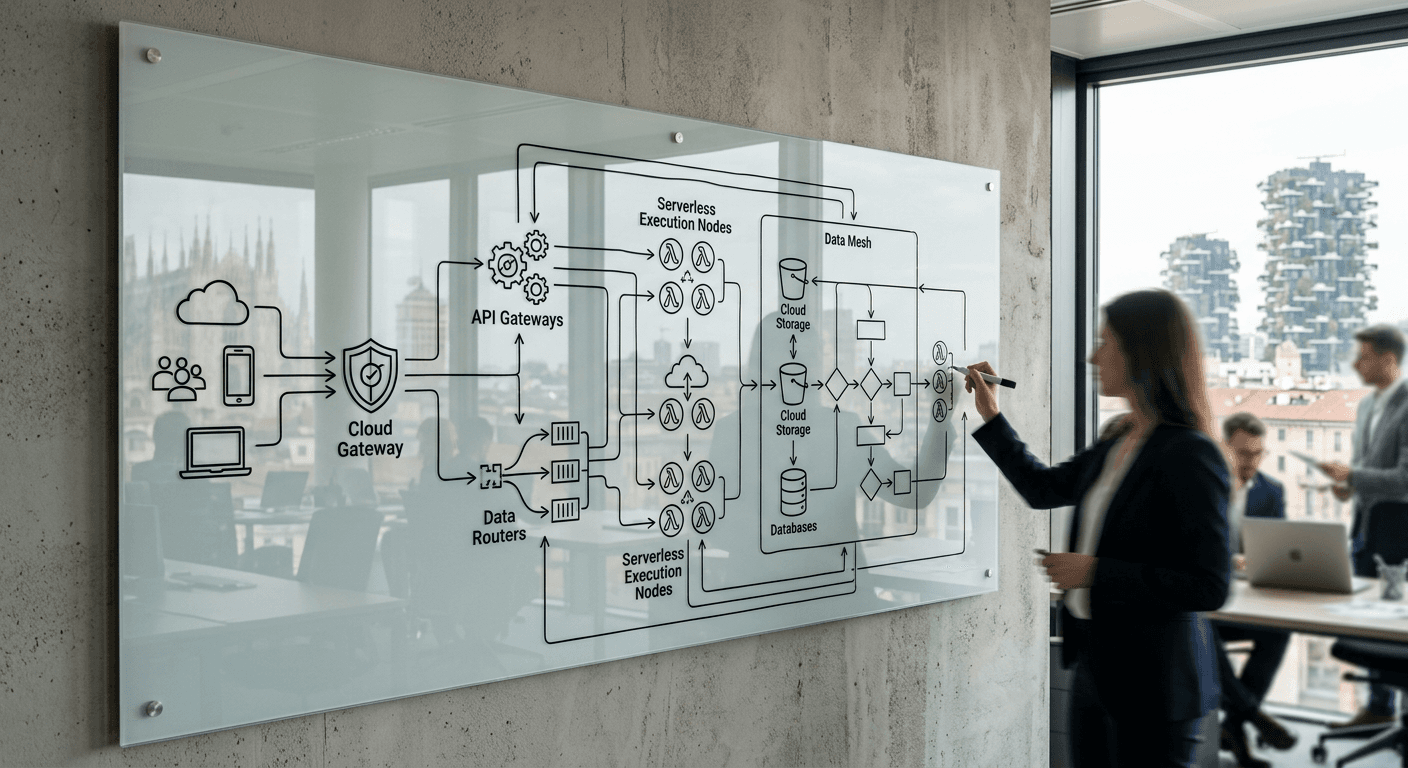
Picture an operations manager at a digital agency in Milan, looking at a spreadsheet containing new lead data, manually copying fields into a client database, and then drafting an identical status update in a messaging channel. They lose fourteen hours a week simply ferrying text between application tabs. The friction here is not a lack of tools, but a failure of integration. When scaling a high-velocity operation, relying on human middleware degrades data integrity and kills response times. Moving this disconnected architecture to a unified power platform eliminates the manual transfer step entirely. Instead of relying on a person to sync state across isolated systems, modern infrastructure requires automated triggers that capture, validate, and route data the moment an event occurs.
Quick Summary
Operational workflow automation replaces the manual transfer of data between business applications with programmable triggers and serverless scripts. It relies on connecting cloud infrastructure to eliminate human data entry, enforce security standards, and ensure high-speed data integrity across hybrid environments.
- Map data flows entirely before writing code to prevent automating broken processes.
- Centralize artificial intelligence prompts to maintain consistent outputs at scale.
- Bridge Microsoft and Google environments using explicit, monitored API handoffs.
- Monitor script execution limits to catch silent workflow failures before they corrupt databases.
Table of Contents
- 1. Map the operational data flow before touching the software
- 2. Centralize your logic components in the cloud
- 3. Build the primary workflow using Power Apps
- 4. Connect peripheral workflows with Apps Script
- 5. Automate reporting with Google Slides AI
- Why infrastructure latency breaks asynchronous automation
- Common Pitfalls & Troubleshooting
- FAQ
- Recommended Reads
1. Map the operational data flow before touching the software
Before provisioning a single cloud resource, you must trace the exact lifecycle of the data you intend to move. Operations teams often rush into connecting endpoints without defining the source of truth, resulting in recursive loops where two systems constantly overwrite each other. When operating a business in cloud environments, data mapping acts as the architectural blueprint that dictates which application holds authority over a specific data state.
Mapping requires identifying the trigger event, the payload structure, and the exact database fields that need updating. If a new client onboarding form generates a webhook, the data map must define whether the CRM or the accounting software assigns the primary client ID. The mechanics involve creating a Business Process Model and Notation (BPMN) diagram that visualizes the state machine. Every API call, conditional branch, and error-handling route must be documented.
The mistake people actually make here is the paved cowpath error. A team will take a fundamentally broken manual process - like emailing CSV files to a manager for approval before uploading them to a database - and simply write a script to automate the emails and uploads. Automating inefficiency only amplifies the error rate. If the manual process involves redundant steps, mapping forces you to cut them out entirely so the data flows directly from the trigger to the destination.
2. Centralize your logic components in the cloud
When deploying artificial intelligence to generate strategic documents, market analyses, or competitor tracking briefs, the logic that governs the output must be isolated from the application interface. If every department uses its own local scripts and fragmented prompt chains, the company loses control over quality, tone, and data compliance.
By routing raw data through a centralized business plan ai module hosted on secure cloud infrastructure, you ensure that every generated document adheres to the exact same logic. The mechanics rely on storing the core instructions and context windows in a dedicated, SOC2-compliant environment. When an endpoint requests an analysis, the workflow sends the raw variables via a secure API POST request to this centralized module, which processes the context and returns the finalized text object.
Organizations fail at this step by hardcoding dynamic variables directly inside their localized automation scripts. When the underlying logic or compliance requirements change, developers must hunt down and rewrite the instructions across dozens of isolated workflows. Centralizing the execution environment means you update the core logic in one place, instantly deploying the fix across every connected application.
3. Build the primary workflow using Power Apps
An automated backend is useless if the internal users feeding it data reject the interface. The primary workflow serves as the ingestion point where human oversight is still necessary, such as approving budget requests or validating localized SEO content before it is published. This is where you deploy power apps to create a secure, predictable front-end that directly binds to your core database.
The mechanics depend on choosing the right architecture. Model-driven applications are inherently bound to Dataverse, meaning the interface automatically structures itself around your established data models. This enforces strict relational data integrity without requiring custom UI development. Canvas applications, conversely, allow precise control over the layout but require manual connections to your data endpoints.
Practical rule: Never use a Canvas application to rebuild a relational data grid; use Model-driven interfaces for heavy data management and reserve Canvas purely for single-task, mobile-first data entry.
The critical mistake developers make in this step is over-engineering row-level permissions at the application layer instead of the database layer. They will write complex logic hiding specific interface buttons based on the user's role. If a user bypasses the app and hits the API directly, the security model fails. Permissions must be enforced at the Dataverse level, ensuring that even if the front-end fails, the core data remains secure.
4. Connect peripheral workflows with Apps Script
Most digital agencies operate in a hybrid reality. The internal operations team might rely on Microsoft infrastructure, while the external clients collaborate exclusively in Google Workspace. Bridging these environments requires explicit, authenticated API handoffs to prevent data silos.
When a file drops into a shared Google Drive or a row is updated in a collaborative tracking sheet, apps script acts as the serverless glue that catches the event and pushes the payload across the boundary. The mechanics involve writing lightweight JavaScript that utilizes the UrlFetchApp class to format an OAuth 2.0 authenticated POST request. This request carries the new data over to a listening webhook on the Microsoft side, seamlessly triggering the next phase of the workflow.
The mistake that destroys these hybrid setups is ignoring execution limits. Google enforces a strict six-minute runtime cap on standard serverless executions. If an agency writes a script to iterate through 5,000 rows of keyword data and update them sequentially, the script will silently timeout at the six-minute mark. Half the database updates, the other half fails, and the system throws no alert. The fix requires utilizing pagination and time-driven triggers to process heavy datasets in distinct batches.
5. Automate reporting with Google Slides AI
Reporting consumes a staggering amount of billable hours. Compiling competitor analysis, monthly traffic growth, and conversion metrics into client-facing presentations is a repetitive task that begs for automation. Instead of manually copying charts from a dashboard, the final step in a mature operational workflow is rendering the data directly into a presentation format.
Leveraging a native google slides ai integration allows your automated workflow to map dynamic spreadsheet ranges directly into specific presentation placeholders. The mechanics require establishing a master template where title tags, text boxes, and image frames are named identically to the JSON keys in your payload. When the end-of-month trigger fires, the script duplicates the master template, fetches the finalized analytics payload, and runs a batch update replacing every placeholder with real-time data.
The most common failure mode here is relying on absolute cell coordinates for data binding. If an operator inserts a new column in the source spreadsheet, a script bound to "Column D" will suddenly start pulling the wrong metrics into the client report. The system will flawlessly generate a completely inaccurate presentation. You must bind the integration to named ranges, ensuring the script pulls the correct data entity regardless of where it physically resides in the sheet.
Why infrastructure latency breaks asynchronous automation
Connecting disparate cloud applications creates a web of asynchronous API calls. When a trigger fires, the system assumes that step A will finish processing before step B requests the resulting data. If the underlying infrastructure suffers from high latency, this assumption collapses and the workflow breaks.
Consider an e-commerce agency routing new customer data through a lead scoring algorithm before inserting it into a CRM. If the lead scoring module takes four seconds to return a value, but the CRM insertion step fires after two seconds, the database records an empty value. This is a race condition. Teams attempt to fix this by adding arbitrary delay timers to their scripts, forcing the workflow to wait ten seconds before proceeding. Delay timers compound rapidly. A workflow with five steps and ten-second delays takes nearly a minute to execute, frustrating internal users who expect instant interface updates.
Preventing race conditions requires high-speed local infrastructure capable of sub-50ms latency. When the data processing layer executes instantly, synchronous API calls return the payload before the next step requests it. Teams deploying an AI-driven SEO for tech companies must ensure their automated content production ties directly into compliant, low-latency environments. Fast infrastructure removes the need for brittle delay timers, allowing operations to scale without corrupting the order of execution.
Common Pitfalls & Troubleshooting
When a cross-platform workflow fails, the visible symptom is almost always the same: the trigger event occurs, but the downstream record remains blank. Diagnosing the failure requires checking the execution logs to identify which of the following root causes broke the chain. The first failure listed below is responsible for the vast majority of silent workflow drops.
Symptom: The workflow triggers, but data never arrives at the destination endpoint.
-
Failure 1: Mismatched JSON schema (Most Common). The source application updated its API and changed a field name from
client_NametoclientName. The receiving webhook still expects the underscore. The payload is successfully delivered, but the receiving system rejects it because the schema does not map correctly. Fix: Check the HTTP response code in the execution history. A 400 Bad Request indicates a schema mismatch. Update the parsing logic in your receiving script to match the new incoming format. -
Failure 2: Expired OAuth refresh tokens. Security protocols require service accounts to periodically refresh their access tokens. If the background refresh script fails, the connection silently degrades. The system attempts to push data but lacks the authority to write it. Fix: Re-authenticate the service account connection in the integration settings and ensure the application requests the
offline_accessscope during the initial handshake so it can generate new tokens automatically. -
Failure 3: Swallowed API rate limits. Every platform restricts how many API calls you can make per second. If a bulk upload triggers 100 simultaneous workflows, the receiving application will return a 429 Too Many Requests status. If your script does not explicitly check for a 429 response, it will mark the execution as successful even though the data was rejected. Fix: Implement exponential backoff in your script. When a 429 error occurs, the script should pause for two seconds, retry, and incrementally increase the wait time until the payload is accepted.
-
Failure 4: Unhandled null values in the payload. A user submits a form without filling in an optional field. The script attempts to parse the null value as a string and throws a type error, halting execution immediately. Fix: Wrap your data mapping variables in conditional statements or use optional chaining operators to provide fallback values (e.g., an empty string) when a field is left blank.
FAQ
How do execution limits affect workflow scalability? Cloud providers limit how long a single automated function can run to prevent server monopolization. If a script processing thousands of rows hits the runtime cap, it terminates forcefully without warning. You must design workflows to process data in small, paginated batches to ensure scalability.
What makes a workflow SOC2 compliant? A workflow meets SOC2 compliance standards when the infrastructure processing the data enforces strict access controls, encrypts data in transit and at rest, and logs every execution event for auditability. Bypassing secure APIs to scrape data or passing unencrypted personal information breaks this compliance.
Can I trigger Microsoft applications from a Google Workspace event? Yes. You can configure a script in the Google environment to execute an HTTP POST request whenever a specific event occurs, such as a file upload. This request sends a structured data payload to a listening webhook endpoint configured in your Microsoft environment, bridging the two systems.
Why do my dynamic presentation binds break during automated syncs? Dynamic binds break when they are mapped to absolute physical locations, such as a specific cell coordinate in a spreadsheet. If the spreadsheet layout changes, the script pulls the wrong data. Binding the script to named ranges ensures it always targets the correct data entity regardless of layout shifts.