Building an AI Business Architecture: Integration Strategies for 2026
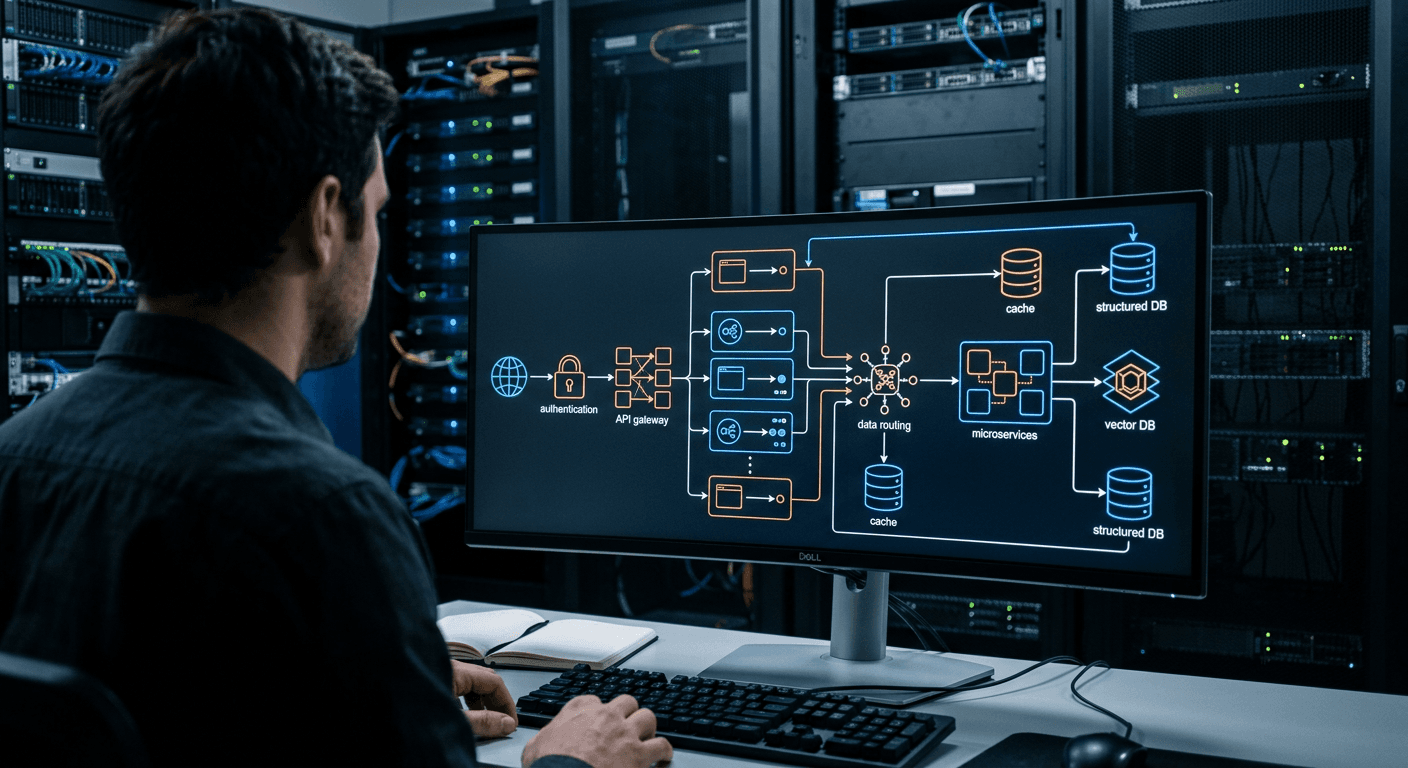
An operations director opens their queue on a Monday morning and sees a backlog of 400 unresolved customer queries alongside a monthly traditional marketing invoice exceeding $6,250. They assume that purchasing an off-the-shelf chatbot and assigning a junior developer to connect it will resolve both issues simultaneously. It will not. "The tool did not work" is not a diagnosis - four different things usually go wrong in this deployment phase, and they require structural fixes, not software updates. Running an ai business architecture requires treating language models as fragile reasoning engines, rather than infallible databases. This guide breaks down exactly how to structure an integration, map your proprietary data pipelines, and measure the precise impact of automation on your operational growth models.
Quick Summary
Integrating artificial intelligence into a commercial operation demands a strict separation between deterministic business logic and probabilistic language generation. Without this division, operations suffer from hallucinated outputs, severe API latency, and uncontrollable token costs that erase any efficiency gains.
- Language models must act strictly as routing and summarization engines, never as primary databases or mathematical calculators.
- Enterprise-grade deployments require sub-50ms latency and 99.99% uptime to prevent user abandonment.
- Retrieval-Augmented Generation (RAG) environments must adhere to SOC2 Type II compliance when processing proprietary company data.
- Operational success should be measured on a strict 75-day growth evaluation window to accurately track organic traffic and lead conversion.
Table of Contents
- 1. Mapping the Operational Data Flow
- 2. Structuring the Architecture
- 3. Deploying Targeted Models
- 4. Constraining the Output Pipeline
- 5. Auditing the Feedback Loop
- Common Pitfalls & Troubleshooting
- FAQ
- Recommended Reads
1. Mapping the Operational Data Flow
Where probabilistic systems break down
Before writing a single line of code, you must audit the specific tasks you intend to automate. The fundamental mechanism of a Large Language Model (LLM) is predicting the next most likely token based on its training data and current context window. It does not "know" your current inventory, and it cannot reliably calculate discounts. When drafting the technical business plan ai integration requires a strict division of labor between your existing relational databases and your new generative models.
If you ask an LLM to generate a personalized email referencing a specific user's subscription tier, the model itself should not query the database. Instead, your backend logic must retrieve the exact tier, price, and renewal date, and then inject those hard facts into the model's prompt. The model's only job is to turn those raw variables into a polite, contextually appropriate paragraph.
The mistake practitioners make here is attempting to automate broken or highly unstructured processes. If your human sales team relies on tribal knowledge and manual spreadsheet checks to quote a price, an AI agent will fail at that exact same bottleneck.
Practical rule: If a task requires deterministic output - like calculating a shipping cost or checking stock levels - route it exclusively to standard logic functions, never to the language model.
To check your readiness today, conduct a time-motion study on the workflow you want to replace. Map every single keystroke and API call your human operators make. If you cannot draw a clear flowchart of where the data comes from, you cannot build an AI agent to execute it.
2. Structuring the Architecture
Why consumer wrappers fail at scale
Transitioning from experimental prompts to a production environment requires upgrading to an ai business class infrastructure. Relying on shared consumer-tier web interfaces or third-party wrappers exposes your operation to unpredictable rate limits, unannounced model deprecations, and severe latency spikes during peak hours.
An enterprise architecture is built entirely on direct API calls routed through a centralized gateway. This gateway handles rate limiting, caches frequent responses, and provides automatic failover if the primary model provider experiences an outage. In high-stakes local search markets, the physical location of your infrastructure matters immensely. To maintain real-time conversations without user abandonment, the system must achieve sub-50ms latency. This requires hosting your application logic and vector databases in cloud regions physically close to your target audience.
The most common failure at this stage is routing sensitive client data through public APIs without a zero-data-retention agreement. If you send customer personally identifiable information (PII) to an external model provider, you are entirely dependent on their security posture. Deploying in environments that maintain strict SOC2 Type II compliance ensures your data handling meets regulatory standards.
If you are currently relying on individual employee accounts to generate copy or query data, you are running an unmanaged shadow IT network. Audit your current AI tooling today and force all organizational usage through a single, centrally logged API gateway.
3. Deploying Targeted Models
The mechanical requirements for automated content
Replacing a traditional marketing expenditure - which routinely exceeds $6,250 a month for manual strategy and content production - requires a system capable of high velocity and strict consistency. Deploying ai services for organic growth is not about generating random blog posts; it requires a coordinated network of specialized agents.
A functional deployment relies on Niche Brand Intelligence. Instead of a single massive prompt, the architecture uses distinct agents for different stages of the pipeline. One agent analyzes competitor search rankings, a second outlines the semantic structure required to compete, and a third drafts the actual text. This multi-agent workflow is how organizations consistently produce 30+ high-quality articles a month without triggering search engine spam filters. Integrating these agents directly into your content management system (like WordPress or Ghost) via API ensures continuous publishing without manual data entry.
Organizations frequently fail here by publishing raw, unoptimized outputs directly to the web. Without an automated content optimization layer or a human-in-the-loop review step, models will confidently generate repetitive phrasing and hallucinated industry statistics.
To see how automated workflows handle the publishing lifecycle securely, review the architecture of integrated AI-driven SEO suites. Today, you can check your own system's viability by reviewing the last five automated outputs generated by your team: if they require more than three minutes of manual editing to match your brand voice, your foundational prompts are missing essential context.
4. Constraining the Output Pipeline
Enforcing boundaries with vector databases
A language model will confidently invent facts to satisfy a user's prompt unless it is strictly constrained by a technique known as Retrieval-Augmented Generation (RAG).
RAG works by converting your proprietary company manuals, product catalogs, and service terms into mathematical representations called vector embeddings. These embeddings are stored in a specialized vector database. When a user asks a question, the system first searches this database for semantically related text chunks. It retrieves only the most relevant paragraphs, injects them into the LLM's prompt, and instructs the model to answer the question using strictly the provided text.
The critical mistake developers make is poor data chunking. If you feed entire 50-page PDFs into the vector database as single chunks, the retrieval system will pull in too much irrelevant data, confusing the model and exceeding context window limits. Embeddings must be broken down by specific topics, headings, and logical breaks.
Furthermore, this database must remain entirely synchronized with your live operations. Review your platform terms of service to understand how data is processed, stored, and protected during these retrieval queries. If your vector database is updated only once a month, your AI agent will offer customers outdated pricing and discontinued products. You can test your current constraints today by explicitly asking your automated agent to quote a product you discontinued last week. If it provides a price, your retrieval sync is broken.
5. Auditing the Feedback Loop
Measuring token spend against lead conversion
An automated architecture is a failure if it generates thousands of conversations but zero commercial conversions. The final step of integration is establishing a rigid measurement loop that ties API token costs directly to organic growth.
Every query your system processes incurs a token cost. If a web scraper or a malicious user traps your AI agent in an infinite loop, your monthly API bill will skyrocket with no corresponding increase in revenue. Measuring success requires tracking the entire funnel: from the initial AI interaction or automated blog post, through the organic search ranking improvement, directly down to the booked consultation or completed sale.
The mistake operators make is evaluating AI projects on an indefinite timeline. AI integrations must be held to the same accountability as human hires. Implementing a strict 75-day growth window allows sufficient time for search engines to index automated content and for behavioral patterns to emerge, without allowing a failing project to bleed capital for a year.
Check your analytics dashboard today. If you cannot trace a specific API token expenditure to a specific user session or published asset, you are flying blind. Implement session tracking IDs immediately to ensure every cent spent on computation maps to a measurable business outcome.
Common Pitfalls & Troubleshooting
When an AI deployment fails in production, the end-user experience usually looks identical: the system outputs nonsense, gives wrong information, or crashes entirely. However, “the AI is broken” is not a useful diagnosis. Below are three distinct failures that manifest similarly, alongside their specific mechanical fixes.
1. The Stale Context Failure
- Symptom: The AI agent speaks perfectly and stays in character, but it confidently offers pricing from six months ago or recommends products that are out of stock.
- Diagnosis: This is the most common real-world cause of failure. The language model is functioning perfectly, but the vector database feeding it is desynchronized from your live inventory or pricing tables.
- Fix: Do not adjust your prompts. Rebuild your data pipeline so that any change in your primary SQL database automatically triggers a re-embedding of that specific text chunk in your vector database.
2. The Model Hallucination Failure
- Symptom: The AI agent answers factual questions with wildly creative, plausible-sounding, but entirely fabricated information (e.g., inventing a new service feature that does not exist).
- Diagnosis: The API's generation parameters are incorrectly tuned for enterprise tasks. The "temperature" setting, which controls the randomness of token selection, is set too high.
- Fix: Hardcode the temperature setting in your API call to 0.1 or 0.0. Creative writing tools benefit from high temperature; operational and customer-service agents require maximum determinism.
3. The Latency Timeout Failure
- Symptom: Users ask a question, the typing indicator spins for ten seconds, and the user abandons the page before the response appears.
- Diagnosis: You have overloaded the model's context window. Sending the entire history of a customer's account alongside a massive system prompt forces the model to process thousands of tokens before generating a single word.
- Fix: Implement aggressive context pruning. Only send the last three conversational turns to the model, and summarize older interactions into a dense, single-paragraph memory string to reduce the processing payload.
FAQ
Do I need a dedicated data science team to deploy these systems? No. The industry has shifted from training proprietary models from scratch to orchestrating existing models via APIs. You need systems engineers and developers who understand API routing, webhook integrations, and database management, rather than data scientists building neural networks.
How does latency impact AI deployment in customer-facing roles? Latency is the primary driver of user abandonment in automated systems. If an API response takes longer than a few seconds, users assume the system is broken and either submit a duplicate query - doubling your token costs - or leave the site. Maintaining sub-50ms latency on the infrastructure side is required to deliver a conversational experience.
Is my proprietary company data used to train public models? It depends entirely on your API agreements. If you use consumer-tier web interfaces, your inputs are often logged and used for model training by default. If you utilize enterprise-tier API endpoints, providers typically offer zero-data-retention policies, ensuring your proprietary data is discarded immediately after the query is processed.
What is a realistic timeline to see ROI on an automated content architecture? While content generation is nearly instantaneous, the operational return on investment relies on search engine indexing and user behavior shifts. A 75-day evaluation window is the standard baseline to measure meaningful changes in organic search traffic and subsequent lead conversion.