Choosing Between Google Vision API and Document AI for Enterprise Data
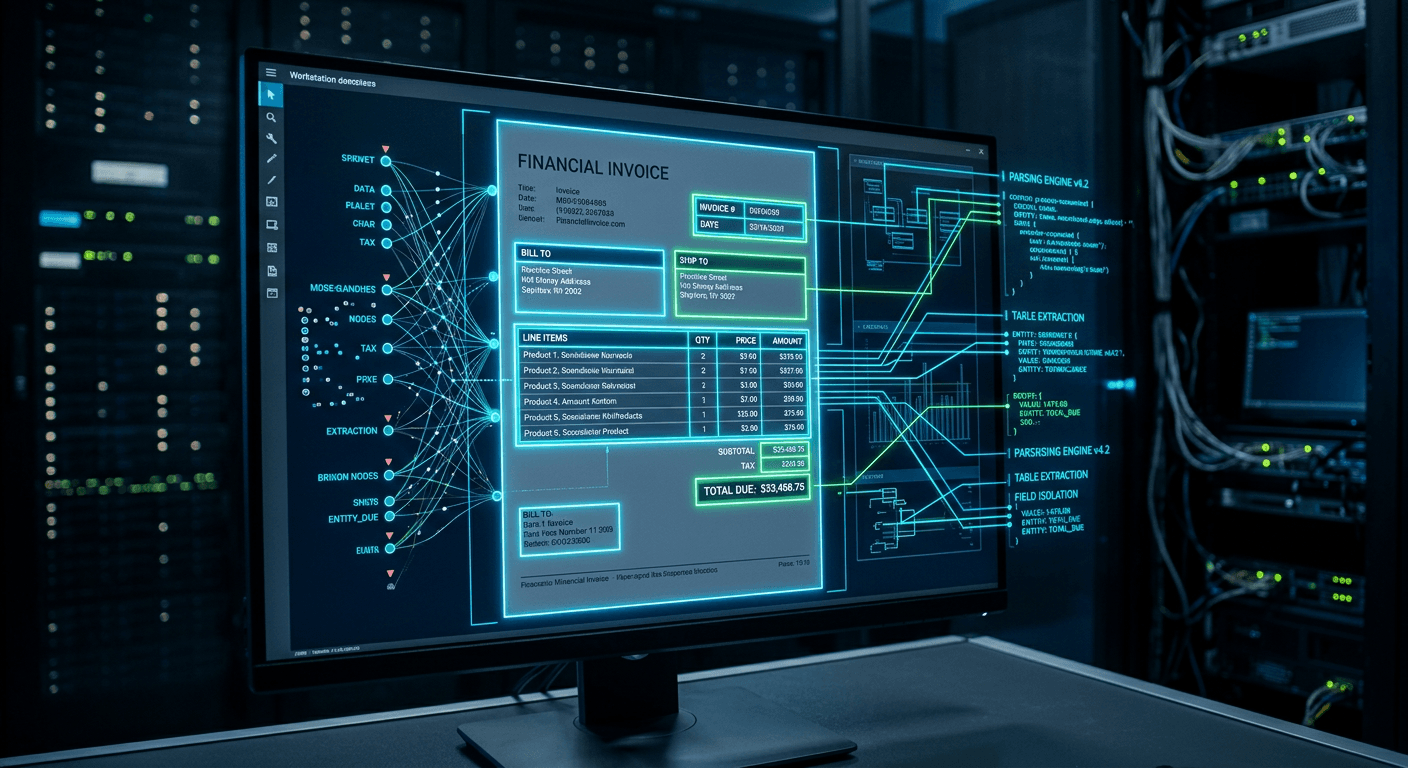
A developer opens the processing queue on Monday morning and sees four hundred rejected digital invoices. The primary error log reads: 'OCR failed to map total amount.' But 'the tool did not work' is not a diagnosis - it is a symptom of an architectural mismatch. Throwing a highly structured financial PDF at a standard image recognition endpoint and expecting clean JSON is a primary reason digital transformation projects stall. A common assumption among engineering teams is that reading text from a digital file is a solved, uniform problem. In reality, identifying the word 'Total' requires completely different mechanics than understanding that the string of numbers adjacent to it represents a final amount due. Knowing exactly when to deploy the google vision api for raw pixel analysis versus a specialized layout parser determines whether an automated workflow scales seamlessly or requires continuous human intervention.
Quick Summary
Enterprise visual artificial intelligence splits into two distinct processing paths: pixel-level object detection and spatial layout parsing. Choosing the incorrect endpoint artificially inflates cloud infrastructure costs and breaks downstream data pipelines.
- Standard optical character recognition reads horizontally, destroying tabular data structures.
- Spatial parsers maintain document geometry, correctly extracting key-value pairs and nested tables.
- Normalizing extracted entities at the API level reduces the need for custom middleware scripts.
- Security compliance dictates that personally identifiable information must be masked before reaching external cloud models.
Table of Contents
- Why Standard Optical Character Recognition Fails on Complex Layouts
- How Spatial Parsing Replaces Flat Text Extraction
- Three Ways Visual Automation Silently Breaks
- Where the Breadth of Processing Costs You
- Who Should Avoid Third-Party Cloud Parsers Entirely
- FAQ
Why Standard Optical Character Recognition Fails on Complex Layouts
The lens through which you must evaluate visual artificial intelligence is structural geometry. The fundamental distinction lies between identifying what an image contains and understanding how a document is organized. Standard optical character recognition operates on a relatively simple premise: a convolutional neural network scans an image, detects high-contrast edges that resemble letters, and outputs a flat string of text.
When you pass a photograph of a storefront to the standard text detection endpoint, the engine returns the words painted on the sign. This is highly effective for unstructured, sparse text. However, applying this exact same mechanism to a digital invoice or a European standard VAT receipt introduces immediate data corruption. Standard OCR engines read text from top-left to bottom-right, strictly horizontally. If a table contains an empty cell in the middle of a row, the horizontal parser skips the empty space and pulls the next available text string leftward. The resulting JSON payload misaligns every subsequent column in that row, associating a tax percentage with a product quantity.
To solve this, developers often write thousands of lines of fragile regular expressions (RegEx) to reconstruct the lost geometry from the raw text strings. This custom middleware breaks the moment a supplier changes their invoice template. Building a custom google ai image pipeline requires understanding that raw text extraction is completely blind to context. It sees the characters '1', '4', and '9', but it possesses no mechanism to determine if those characters represent a product weight, a date, or a currency value. You can check this limitation today: submit a three-column PDF to a basic OCR endpoint and observe how the output collapses into a single, unreadable paragraph block.
How Spatial Parsing Replaces Flat Text Extraction
Structured extraction requires a model trained not just on character shapes, but on spatial dependencies. This is where google document ai diverges from basic computer vision. Instead of outputting a flat text string, specialized document processors utilize transformer-based machine learning architectures to map the entire geometry of the page before attempting to read a single word.
The system first draws bounding boxes around distinct visual regions - identifying a cluster of text as a 'header', a grid of lines as a 'table', and a block of fine print as 'terms and conditions'. Only after the structural hierarchy is established does the engine extract the text within those boundaries. This spatial awareness allows the model to identify key-value pairs based on their proximity and visual styling. It understands that a bolded 'Invoice Date:' string physically adjacent to '24/10/2026' constitutes a linked entity.
More importantly, spatial parsers perform entity normalization at the point of extraction. If an Italian vendor submits a receipt reading '24 Ottobre 26', the processor does not merely return that raw Italian string. The underlying model identifies the string as a date entity and returns an ISO 8601 standardized value: 2026-10-24. This shifts the burden of data formatting away from your internal engineering team and onto the cloud provider.
Practical rule: Never use standard optical character recognition for files containing grid lines, nested columns, or distinct key-value pairs; always route structured layouts to a dedicated spatial parsing processor.
Automating this extraction at scale often requires integrating these visual data streams into broader marketing and visibility pipelines, utilizing AI-driven SEO for tech companies to trigger high-speed content production based on the extracted entities. A properly extracted product specification sheet immediately becomes structured JSON that can populate an e-commerce database, driving organic search visibility without manual data entry.
Three Ways Visual Automation Silently Breaks
When a visual processing pipeline fails, it rarely crashes the application. Instead, it silently passes corrupted data into your production database. Diagnosing these failures requires looking past the API response code and examining the extraction mechanics.
The Left-to-Right Table Collapse
The most common failure in financial automation occurs when processing line items. As established, horizontal reading destroys vertical columns if a cell is empty. But the failure also triggers when text in one column wraps to a second line, while the adjacent column does not. The parser reads the first line of column A, the first line of column B, and then returns to the second line of column A, creating an interleaved, nonsensical text string.
The symptom is a database populated with merged product descriptions and prices. The immediate check is to look at the JSON output for newline characters \n embedded randomly within what should be a single entity. The fix is strictly architectural: transition from a raw text endpoint to a dedicated table-parsing endpoint that anchors data to vertical grid boundaries rather than horizontal text flow.
Uncalibrated Confidence Thresholds
Every extracted entity returns with a confidence score ranging from 0.0 to 1.0, indicating the model's certainty. A critical mistake engineering teams make is setting a global, document-wide confidence threshold. If a developer sets a flat rule rejecting any document with a score below 0.85, they will block perfectly valid invoices simply because the engine was only 70% confident about a smudged vendor logo.
Conversely, accepting a 0.85 confidence score for a final tax amount introduces unacceptable financial risk. The fix requires granular, field-level threshold logic.
Practical rule: Never set a global confidence threshold for an entire document; assign 0.95+ thresholds to financial totals and core identifiers, while allowing 0.60 thresholds for unstructured vendor descriptions or secondary addresses.
The Resolution and Latency Trap
Field agents and end-users frequently upload visual data via mobile devices, generating raw files that exceed 12 megapixels. Passing a 15MB photograph directly to a cloud parsing endpoint consumes massive bandwidth, triggers payload size limits, and drastically increases processing latency. Processing a high-resolution image does not yield proportionally higher text accuracy; in fact, extremely high resolutions can sometimes confuse models trained on standard document dimensions.
The symptom is a processing queue that times out or takes several seconds per file, ruining the user experience in synchronous application flows. The actionable check is to monitor the average payload size hitting your API gateway. The fix is enforcing client-side downsampling. Resizing mobile uploads to a maximum width of 1024 pixels preserves text legibility while dropping payload sizes to under 500KB, allowing enterprise systems to maintain the sub-50ms latency required for real-time applications.
Where the Breadth of Processing Costs You
Cloud providers price their visual processing endpoints based on the complexity of the underlying model. Choosing a model that extracts more features than you need directly impacts unit economics. You must map the API selection to the specific business requirement rather than defaulting to the most powerful tool available.
| Specification | Raw Object Detection | Spatial Document Parsing |
|---|---|---|
| Primary Engine | Convolutional Neural Networks (CNN) | Transformer-based Layout Models |
| Data Structure | Unstructured (Photographs, street scenes) | Structured (Forms, invoices, contracts) |
| Output Format | Flat strings, generalized labels, coordinates | Hierarchical JSON, key-value pairs, entities |
| Pricing Model | Priced per 1,000 image units (features calculated separately) | Priced per page (often 5x to 10x the cost of raw image processing) |
| Normalization | None (returns raw strings) | High (formats dates, currencies, standardizes addresses) |
| Latency Profile | Highly optimized, synchronous real-time | Higher computational overhead, often requires asynchronous queuing for multi-page PDFs |
If your platform needs to detect whether a user uploaded a picture of a passport or a driver's license for initial routing, using a heavy layout processor is a waste of capital. A basic label detection model can classify the document type in milliseconds for a fraction of a cent. Once the document type is confirmed, you then route it to the more expensive, specialized parser only when extracting the specific structured fields is strictly necessary.
Who Should Avoid Third-Party Cloud Parsers Entirely
Not every digital transformation project should rely on external cloud extraction endpoints. Organizations processing highly classified intellectual property, or those operating in heavily regulated healthcare and defense sectors, must evaluate the data persistence policies of third-party APIs.
While enterprise cloud providers operate within SOC2 Type II compliance frameworks and generally offer data processing agreements that prevent your payloads from being used to train public models, the data still physically leaves your infrastructure. If your application handles unredacted personal health information or classified government schematics, transmitting that data across the open internet - even via encrypted TLS connections - often violates internal risk mandates or localized data sovereignty laws.
These organizations should skip cloud APIs entirely. Instead, they must deploy localized, on-premises parsing models hosted strictly within their own air-gapped server environments. Furthermore, companies processing strictly digital-native PDFs (files generated directly by software, containing a selectable text layer) should never use visual AI models. If a PDF already contains an embedded text layer, using a simple open-source text extraction library is instantly accurate and computationally free. Subjecting a digital-native PDF to a visual machine learning model introduces unnecessary costs and the artificial possibility of extraction errors.
FAQ
Can I use basic image recognition to process digital receipts for VAT compliance?
No. Basic image recognition extracts flat text strings without spatial context. European VAT compliance requires explicit linkages between tax percentages, net amounts, and vendor identification. Only spatial parsers can reliably maintain these key-value relationships.
How do these APIs handle multi-page digital documents?
Standard image APIs process single image frames. To process a 50-page PDF, you must split the document into individual image files, send 50 separate synchronous requests, and stitch the responses together. Specialized document APIs accept multi-page PDFs natively, processing them asynchronously and returning a single unified JSON payload.
Does document rotation or skewed scanning affect the extraction accuracy?
Modern spatial parsers automatically detect document orientation and digitally deskew the image before extraction. However, severe warping (like a crumpled piece of paper photographed at a sharp angle) distorts the physical distance between key-value pairs, which can cause the bounding box logic to fail.
What happens if a critical field is obscured by a physical stamp or signature?
The model will return a very low confidence score for that specific region, or omit the entity entirely if the text is completely illegible. This is why automated pipelines must rely on field-level confidence thresholds to trigger human-in-the-loop review for obscured entities.