Deploying google ai for technical content pipelines: A step-by-step guide
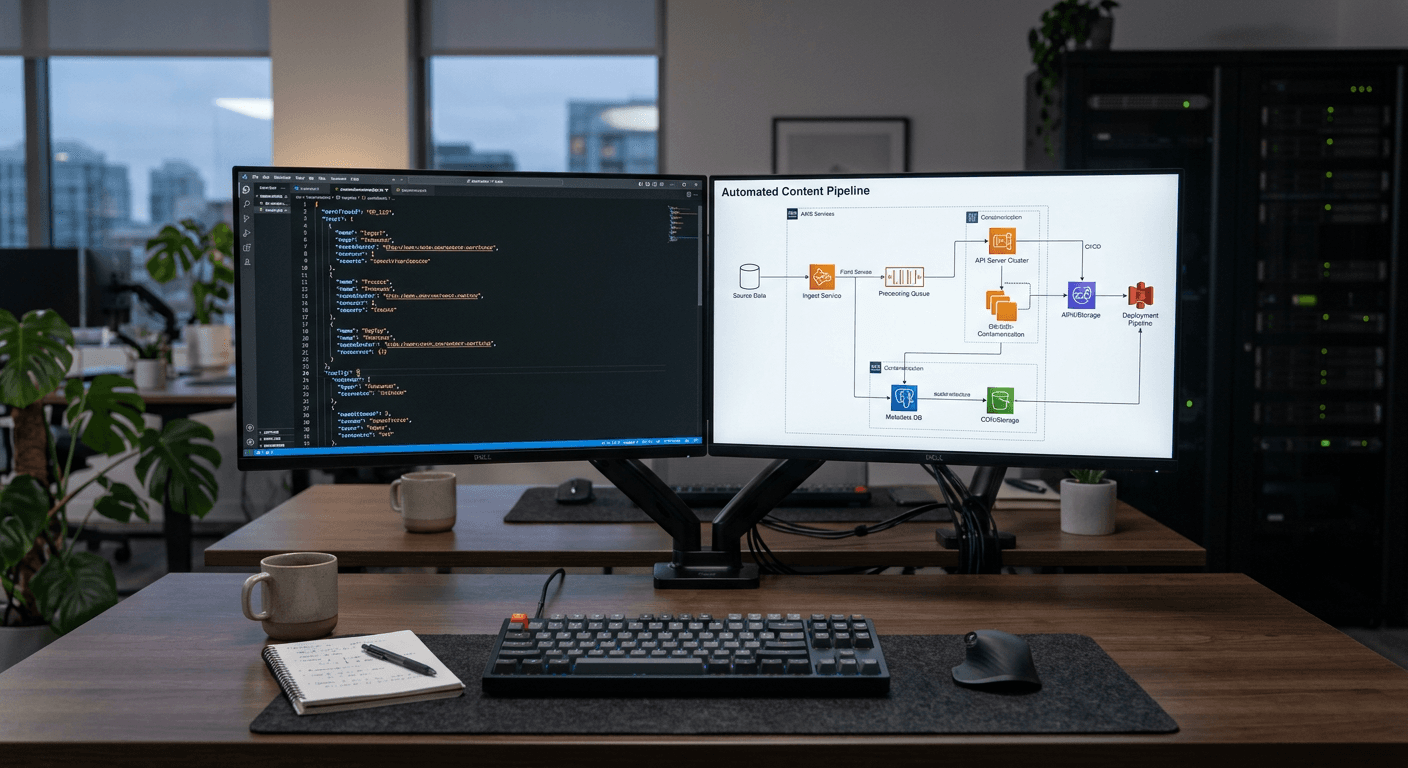
When a technical SEO team attempts to scale an automated content production pipeline from ten articles a month to thirty, the cloud infrastructure rarely fails. The breaking point is almost always how they configure their initial deployment of google ai. Dropping a raw editorial brief into a standard conversational interface and expecting a production-ready, technically accurate draft fundamentally misunderstands how token prediction mechanisms operate. You end up receiving a superficial summary rather than the structural depth required to rank in competitive B2B software markets or convert enterprise leads. Building a reliable system requires abandoning the chat interface entirely and constructing a structured, multi-stage pipeline.
Why a basic google ai deployment breaks at scale
A complete google ai overview reveals that consumer-tier interfaces are designed for conversational safety and brevity, not for generating comprehensive technical documentation or authoritative market analysis. When you rely solely on a basic google ai assistant, the model optimizes for a quick, acceptable response rather than deep technical exploration. It frequently utilizes a high temperature setting that introduces variability - a trait that is actively detrimental when generating strict compliance documentation or precise coding tutorials. Furthermore, the underlying attention mechanism dilutes over long continuous threads, causing the system to forget formatting constraints established in your very first prompt. To achieve professional productivity, you must transition from treating the model as an intelligent search engine to managing it as a deterministic processing engine. This means isolating tasks, defining strict contextual boundaries, and utilizing API integrations that offer repeatable, low-latency execution.
Quick Summary
Deploying these models for professional productivity requires structured context grounding, multi-stage prompt chaining, and strict validation checks to prevent structural drift and hallucination. Moving beyond a basic conversational interface involves configuring API endpoints or workspace tools to execute repeatable, technically accurate workflows that preserve output formatting.
- Establish explicit context boundaries and system instructions before generating technical content.
- Chain distinct prompts for outlining, drafting, and reviewing to maintain technical depth.
- Validate all outputs against strict formatting constraints and internal data compliance standards.
- Deploy automated pipelines with zero-retention policies for secure publishing integration.
Table of Contents
- Why a basic google ai deployment breaks at scale
- Quick Summary
- 1. Setting up the base context window
- 2. Structuring the multi-stage generation pipeline
- 3. Enforcing technical constraints and brand voice
- 4. Validating output against data compliance standards
- 5. Automating the ingestion and publishing flow
- Common Pitfalls & Troubleshooting
- FAQ
- Recommended Reads
1. Setting up the base context window
Why isolated environments outrank continuous chats
The foundational step in building a reliable generation pipeline is understanding the limitations of the effective retrieval window. Even when a language model boasts a massive token limit, its retrieval accuracy degrades significantly in the middle of long contexts - a phenomenon known as the "lost in the middle" effect. If you run an ongoing marketing campaign inside a single continuous thread, the model inevitably begins referencing obsolete parameters, tone guidelines, or topic constraints from three weeks prior. Early iterations, such as google bard ai, demonstrated this limitation clearly when prolonged conversations led to entirely hallucinated operational rules. The attention mechanism simply cannot weigh a month of conversation history accurately against an immediate instruction.
The mistake most operators make is treating the interface like a human employee who benefits from remembering last week's meeting. In reality, a stateless architecture produces vastly superior results. You must initialize a completely fresh environment for every single asset you produce, loading only the exact context required for that specific task.
Practical rule: Always initialize a fresh API session with a standardized system prompt rather than relying on previous conversation history to carry the context forward.
Check your current workflow today: if you are scrolling up to see the previous article you generated before typing a new prompt, your context window is already contaminated. Switch to a dedicated workspace where the system instructions are hardcoded and loaded entirely from scratch upon execution.
2. Structuring the multi-stage generation pipeline
Single-prompt generation limits structural depth
Requesting a complete 2,000-word technical guide in a single prompt is a guaranteed path to shallow, repetitive text. Token generation probability flattens over long, unbroken outputs without intermediate anchor points. The mechanics of modern architectures, including the gemini google ai framework, dictate that the model performs best when predicting shorter, highly constrained sequences. When you front-load a massive prompt containing your brand voice, the desired outline, the keywords, and the call to action, the model effectively averages these instructions, diluting the specificity of each.
The standard failure here is the "all-in-one" prompt. Operators ask for the introduction, the body paragraphs, and the conclusion simultaneously. The result is a draft where every section feels rushed, and complex technical arguments are summarized into bullet points rather than explored in depth.
To construct a professional pipeline, break the generation into chained, sequential steps. Stage one is purely for knowledge retrieval and structuring: instruct the model to generate only an exhaustive outline. Once a human or an automated rule-set validates that outline, pass it to stage two. Stage two involves prompting the model to draft only section one, using the validated outline as strict context. Stage three drafts section two, and so on. By forcing the model to generate one specific segment at a time, you maximize its attention on those immediate technical details, resulting in a significantly denser and more authoritative final document. Check your workflow today by splitting your next prompt into three distinct stages and comparing the structural depth of the output.
3. Enforcing technical constraints and brand voice
Where generic tone settings fail technical reviews
Instructing a language model to be "professional, authoritative, and engaging" accomplishes virtually nothing. Adjectives leave token selection entirely up to the model's training data average, which inevitably sounds exactly like every other generic blog post on the internet. The mechanics of precise generation require negative constraints and exact rule arrays. A specialized google writer setup demands syntactical boundaries that force the model to exclude high-probability, low-value words.
The common mistake is relying on persona adoption - "Act like a senior cybersecurity expert" - instead of providing explicit constraint parameters. While persona adoption helps shift the general vocabulary, it does not prevent the model from using enthusiastic marketing fluff that destroys credibility in technical circles.
Instead of adjectives, supply concrete operational rules. A robust system prompt should state: "Never use exclamation marks. Write strictly in the active voice. Do not use the words 'unlock', 'leverage', 'transform', or 'delve'. If citing a physical dimension, use metric units exclusively." By banning the most common filler transition tokens, you force the attention mechanism to select lower-probability, higher-specificity technical terms to complete its sentences. You can act on this today by auditing your current prompt library: delete every adjective describing the tone and replace each one with a concrete rule about what the output is absolutely forbidden to do.
4. Validating output against data compliance standards
How unverified generation introduces security risks
Integrating generative language models into an agency or enterprise workflow introduces immediate data classification risks. The mechanics of consumer-tier web applications often involve logging input prompts and generated outputs for continuous model training. Pasting proprietary client server architectures, unreleased software product specs, or internal pricing models into these public-facing interfaces violates basic non-disclosure agreements and strictly prohibits achieving SOC2 Type II compliance standards.
The critical failure mode here is treating all input fields equally. Teams routinely paste sensitive database schemas into standard chat windows simply to generate API documentation faster, unknowingly exposing that architecture to public training sets.
The solution is establishing a strictly compliant environment by migrating from consumer interfaces to enterprise-grade API endpoints that guarantee zero data retention. Establishing these pipelines means filtering exactly what data is permitted to leave your local network. Analyzing the architecture of a dedicated RapidWombat - AI-Driven SEO for Tech Companies platform demonstrates how sub-50ms latency environments are designed to process generative requests without logging sensitive payload data for public pools. Verify your current compliance status today by checking the terms of service of the endpoint you are using: if it does not explicitly state a zero-retention policy for API inputs, you must immediately halt the ingestion of proprietary client data.
5. Automating the ingestion and publishing flow
Manual extraction breaks the speed advantage
If a technical team generates text efficiently but relies on a human operator to copy, format, and paste the output into a Content Management System like WordPress or Ghost, the operational bottleneck simply shifts downstream. Copy-pasting from a browser interface introduces severe formatting drift. Markdown headers are frequently flattened into bold text, numbered lists break their sequence, and code blocks lose their syntax highlighting. The mechanics of a true automated pipeline require direct API-to-CMS handoffs that preserve the Abstract Syntax Tree (AST) of the document.
The mistake is keeping the generation phase and the publishing phase as two entirely separate operational ecosystems. A production-ready pipeline requests the text output in a strict schema - typically JSON or pre-formatted HTML - validates the payload programmatically, and pushes it directly to the staging environment via webhook.
To build this, you must mandate strict output formatting in your final prompt stage. Instruct the model to return the final assembled article wrapped entirely in a designated JSON structure, separating the title, the meta description, and the body content into distinct key-value pairs. This eliminates human formatting latency entirely. You can implement this today by adjusting your final generation prompt to explicitly reject conversational pleasantries (like "Here is your article:") and output only parseable markdown or JSON, ready for immediate programmatic routing.
Common Pitfalls & Troubleshooting
When automated content pipelines degrade, the symptoms often look identical to the end user: the text reads poorly and fails to rank. However, the underlying root causes require highly distinct technical interventions. Diagnosing these failures accurately is what separates an experimental setup from a production-grade system.
1. The context collapse (Most Frequent Cause)
- Symptom: An article that begins as a highly technical, constrained breakdown inexplicably turns into a generic, high-level overview by the fourth subheading.
- Cause: The generation has exceeded the effective retrieval window, pushing the initial system prompt and brand voice constraints out of active memory. The model reverts to its baseline training weights.
- Fix: You must re-inject the primary persona, negative constraints, and formatting rules at the top of every single API call or section prompt within the multi-stage chain, rather than assuming parameters carry over indefinitely.
2. The transition loop
- Symptom: The model ends every single section with phrases like "In conclusion" or starts every paragraph with "Furthermore" and "Ultimately."
- Cause: The attention mechanism is overweighting its own previous outputs, falling into a predictable token loop where it uses syntactical bridges to lower the processing cost of shifting topics.
- Fix: Add a negative constraint array to your system prompt specifically banning these transitional filler phrases. This forces the model to rely on structural logic and technical data rather than lazy linguistic bridges.
3. The formatting drift
- Symptom: Bullet points suddenly become numbered lists, H3 tags revert to standard bold text, or markdown tables collapse into comma-separated text.
- Cause: The model prioritizes linguistic completion over markdown compliance when token limits get tight, effectively abandoning structural rules to finish a sentence.
- Fix: Mandate a strict schema format for the output and run an automated validation script on the payload before it hits the CMS. If the script detects broken markdown, it should automatically trigger a regeneration of that specific section.
4. The hallucinated metric
- Symptom: A perfectly formatted comparison table contains server latency pricing data that is completely fabricated.
- Cause: The prompt asked the model to compile data without providing a strict failure state for missing information. The model optimized for completing the table rather than verifying the data.
- Fix: Explicitly instruct the model to return a specific error string (e.g., "DATA_MISSING") if the context window does not contain the required numerical value, strictly forbidding it from predicting a plausible but fake number.
FAQ
Does utilizing automated text generation impact organic search rankings? Search engines evaluate the depth, structure, and user utility of the text, not merely the mechanism of its creation. If you deploy a structured pipeline that enforces technical depth, unique structural formatting, and strict accuracy, the origin of the text does not automatically trigger a penalty. Systems fail when they output superficial, low-effort summaries that offer no new information to the market.
How do you prevent hallucinated statistics in technical articles? The only reliable method is strict context grounding. Provide the exact reference data, whitepapers, or pricing arrays within the prompt's context window. You must explicitly instruct the system to rely only on the provided variables and to output a designated error code if a requested metric is absent, rather than allowing it to fill the gap with statistical averages from its training data.
Can a single prompt handle both complex formatting and stylistic tone? Rarely with any consistency. Combining complex structural instructions (like nested JSON outputs) with nuanced tone constraints confuses the attention mechanism. It is far more effective to separate these tasks into a pipeline: generate the technical structure and factual content first, then run a secondary processing pass strictly for stylistic alignment and formatting validation.
What is the primary risk of using consumer interfaces for enterprise content? The primary risk lies in data retention policies and regulatory compliance. Consumer interfaces frequently log inputs to be reviewed by human operators or utilized for continuous model training. Submitting proprietary network architectures, client data, or unreleased product specifications through these portals directly violates enterprise security policies and compliance frameworks like SOC2.
Recommended Reads
- Review the privacy framework for RapidWombat - AI-Driven SEO for Tech Companies
- Examine the terms of service at RapidWombat - AI-Driven SEO for Tech Companies