Enterprise AI Architecture: Scaling Google DeepMind and Document Processing
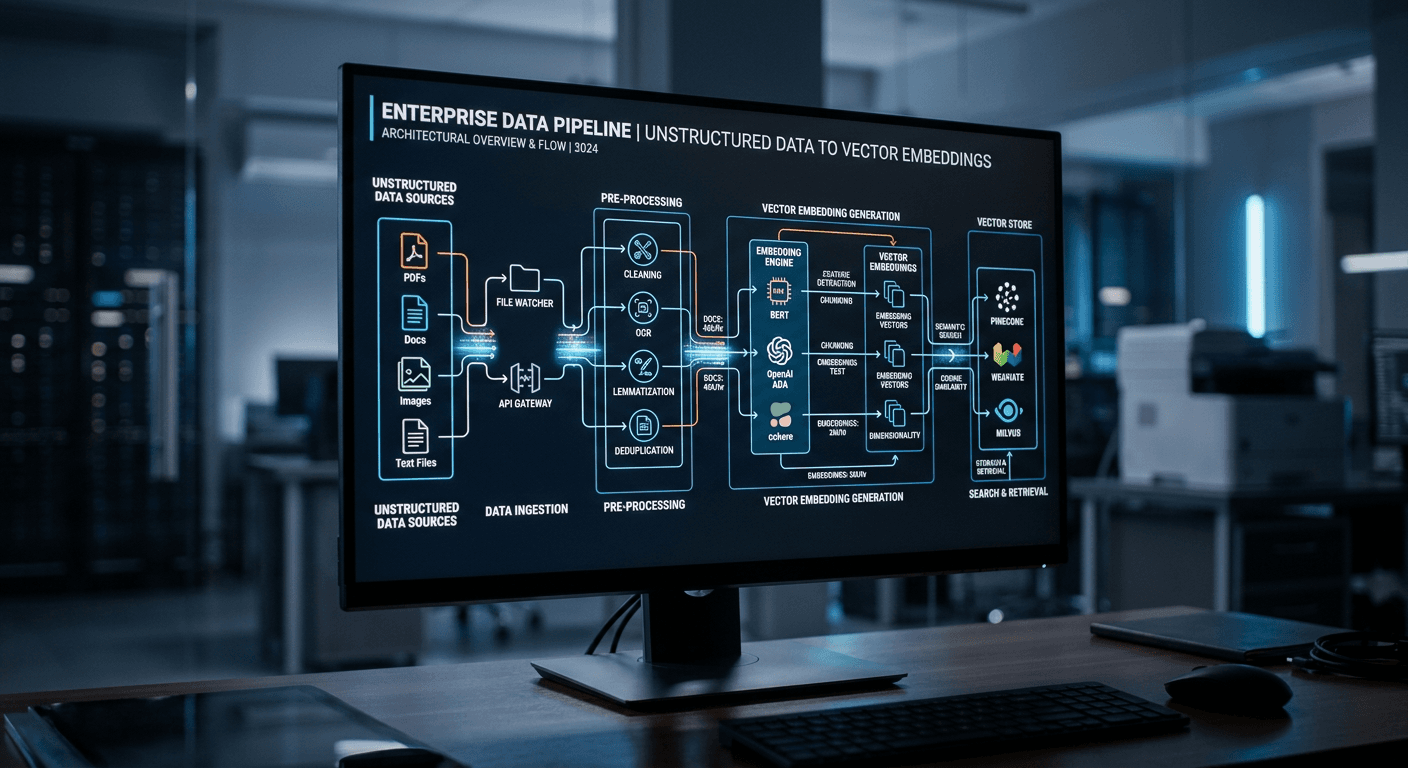
Most IT companies map their generative AI pipelines backward, starting with a chat interface and ignoring how the foundational model parses the underlying data. When engineering teams bolt on an API without structuring the backend for vector retrieval, the output inevitably hallucinates business facts. The reality of enterprise AI is that models rely entirely on structured, compliant data ingestion. Whether you are building internal search agents or automating localized SEO content, evaluating Google DeepMind research against your actual latency and SOC2 compliance constraints is what determines whether the system survives production.
Quick Summary
Enterprise AI deployment requires integrating specialized foundational models with compliant, low-latency infrastructure to convert unstructured data into verifiable, semantic output.
- Specialized document processors reduce token hallucination better than raw LLM ingestion.
- Vector search mechanisms require strict latency thresholds to prevent agent timeouts.
- Multimodal generation mandates asynchronous indexing for search visibility.
- API rate limits determine whether a prototype can scale into an automated production pipeline.
Table of Contents
- Why Google DeepMind deployments expose legacy infrastructure flaws
- Where spatial document processors fracture the data pipeline
- How embedding logic dictates indexation mechanics
- Why latency dictates survival under modern crawlers
- When generative media stalls rendering pathways
- Which throughput limits force an enterprise tier upgrade
- FAQ
- Recommended Reads
Why Google DeepMind deployments expose legacy infrastructure flaws
The shift from text-only transformer models to native multimodal processing forces a fundamental architectural change in how enterprises handle data. Foundational models developed by Google DeepMind do not simply read text strings in isolation; they process raw byte streams of audio, visual, and textual data simultaneously. This concurrent processing mechanism requires massive localized computational bandwidth and highly optimized network routing. When an IT firm attempts to route these multimodal payloads through standard cloud environments, the system chokes on the tokenization of mixed media.
Latency spikes occur because the backend must serialize complex data structures before the API can even accept the prompt. An infrastructure relying on traditional relational database queries bottlenecks immediately when trying to feed heavy context into these advanced models. Standard REST protocols are often insufficient for the sustained streaming connections required by continuous multimodal inference.
To sustain a production environment, you must transition to cloud architecture capable of handling high-throughput vector transactions natively. Operating within an infrastructure that guarantees 99.99% uptime becomes a baseline necessity rather than a premium feature. Without a rigorous, localized cloud setup, the application layer times out before the model finishes inference, leaving the end-user with a hanging connection and breaking automated content pipelines entirely. The core task is replacing synchronous database calls with asynchronous data streams that feed directly into the model's context window.
Where spatial document processors fracture the data pipeline
Many engineering teams assume PDF data extraction is a solved problem, relying on basic optical character recognition (OCR) to feed their AI pipelines. This approach destroys the spatial reality of business documents. Raw OCR dumps text top-to-bottom without spatial awareness, flattening hierarchical headings and scrambling table columns. If you pass this flattened string into a foundational model, the AI inevitably hallucinates the relationship between a header and its corresponding financial figure, because the visual space connecting them has been erased.
Implementing Google Document AI replaces this raw text dump with spatial understanding. It maps bounding boxes to textual elements, calculating the X and Y coordinates of every word on the page. The processor outputs a deeply nested JSON structure that preserves the exact layout of a compliance report, an invoice, or a technical manual. The model understands that a value sits in the third column of the second row, rather than just appearing somewhere on page four.
Practical rule: Never feed raw OCR text directly into an LLM context window; always route unstructured files through a spatial document processor to maintain table grids and heading hierarchies before vectorization.
This structured ingestion is mandatory for maintaining strict SOC2 Type II compliant data practices. Proprietary business data must be parsed accurately before it is stored or queried to ensure that permissions apply to the correct data objects. A failure at the document extraction phase cascades through the entire system, rendering downstream AI agents entirely unreliable. Teams must validate the spatial JSON outputs against the original document geometries before committing the data to a vector store.
How embedding logic dictates indexation mechanics
Moving from lexical keyword matching to vector-based retrieval alters how a platform must structure its content for visibility. Modern search AI relies on dense vector embeddings, which are mathematical representations of semantic meaning plotted in high-dimensional space, rather than counting the frequency of specific text strings. When a user or an automated agent queries a database, the system calculates the cosine similarity between the query's vector and the chunked documents in the database.
The primary failure mode here lies in the chunking strategy. If an enterprise feeds an entire 50-page technical manual into the embedding model as a single block, the resulting vector becomes a diluted average of too many conflicting concepts. The cosine similarity to any specific, targeted query degrades, and the AI agent returns irrelevant results or hallucinates a summary.
Instead, data must be segmented into semantic chunks of roughly 300 to 500 tokens, utilizing overlapping text windows to preserve the context across chunk boundaries. This granular approach ensures that when an automated agent scans the repository, it retrieves the precise paragraph containing the answer. Utilizing a compliant data architecture - such as an AI-driven SEO platform for tech companies - ensures these embeddings are organized, securely stored, and served with the low latency required for real-time visibility in hyper-local search markets.
Why latency dictates survival under modern crawlers
As the landscape shifts toward AI-summarized answers, the tolerance for slow infrastructure has disappeared. An AI-driven crawler does not wait for a bloated JavaScript payload to render on the client side. If a server fails to deliver the initial HTML payload within strict latency windows, the crawler abandons the session and downgrades the site's visibility. Google search AI systems prioritize sources that provide immediate, machine-readable context without requiring heavy computational overhead to discover the primary entities.
This creates a direct correlation between hardware performance and market visibility. An architecture delivering sub-50ms latency ensures that automated agents can ingest and index the content without connection timeouts. E-commerce platforms and software startups that rely entirely on client-side rendering for their core content often find themselves omitted from AI summaries. This omission occurs not because their content is poor, but because their infrastructure is too slow to participate in the semantic crawl.
Practical rule: Serve all critical text content via static HTML or edge-rendered endpoints; never force an AI crawler to execute client-side scripts to discover your primary entities.
To correct this, engineering teams must shift their rendering strategies. Pre-computing static pages at build time and deploying them to edge nodes drastically reduces the Time to First Byte (TTFB). By the time the AI crawler initiates the handshake, the fully parsed text is already waiting in a localized data center, completely bypassing the backend application servers.
When generative media stalls rendering pathways
Dynamic image generation introduces catastrophic payload overhead when integrated poorly into a web architecture. Implementing a Google AI image endpoint to generate visual assets on the fly during a user's active session guarantees a degraded rendering pathway. The latent space diffusion process involves iterative denoising steps that inherently require seconds to complete. This is an unacceptable delay for web performance standards, which measure success in milliseconds.
The common mistake is treating generative media like a standard database query. When a site requests image generation synchronously at render time, the entire page load stalls waiting for the API response. The server thread is blocked, memory usage spikes, and the end-user stares at a blank screen.
Enterprises must separate media generation from the rendering pathway entirely. Assets must be generated asynchronously in a background queue. Once the image is created, the system must compress it into a modern format like WebP or AVIF and cache it across a Content Delivery Network (CDN). The frontend application then requests the static, pre-computed asset rather than invoking the generative model. This asynchronous workflow preserves the performance metrics required for high search visibility while still leveraging automated asset creation.
Which throughput limits force an enterprise tier upgrade
Scaling an automated content pipeline from a handful of manual prompts to thousands of weekly autonomous executions exposes the strict rate limits of standard API tiers. When a production environment hits a requests-per-minute (RPM) ceiling, the pipeline does not merely slow down; it drops payloads, resulting in malformed JSON responses, incomplete data structures, and broken site pages. Upgrading to Google AI Pro provides the necessary throughput, but it shifts the engineering challenge from availability to cost management.
The primary consideration becomes the token-to-cost ratio. A model operating with a massive context window allows for entire codebases or lengthy technical documents to be processed in a single prompt. However, passing hundreds of thousands of tokens per request rapidly consumes the budget if the task only required extracting a single data point. Engineering teams must implement strict prompt pruning and utilize smaller, specialized models for basic routing tasks.
Model Comparison Table
| Feature Dimension | Standard Tier API | Google AI Pro Tier | Local Open-Source Deployment |
|---|---|---|---|
| Throughput (RPM) | Strictly throttled | High limits / Priority queue | Hardware dependent |
| Context Window | Standard (up to 32k) | Extended (up to 1M+ tokens) | VRAM limited (typically 8k-32k) |
| Latency Predictability | High variance during peak | SLA-backed consistency | Predictable but hardware-bound |
| Best Use Case | Prototyping, low-volume | High-volume automated pipelines | High-privacy offline environments |
| Cost Structure | Pay-as-you-go (low base) | Pay-as-you-go (high scaling) | High upfront CapEx, low OpEx |
Reserving the high-tier, priority-queued models exclusively for complex reasoning and generation ensures the pipeline remains profitable. You should not use a premium tier model to perform basic text classification that a local, lightweight vector operation could handle for free.
FAQ
How does document processing differ from standard OCR?
Standard OCR translates images of text into flat strings, ignoring the physical layout of the page. Advanced document processing uses spatial mapping to understand bounding boxes, preserving the relationship between columns, rows, and hierarchical headings in a structured format like JSON.
What is the optimal chunk size for vectorizing enterprise data?
For most semantic search applications, segmenting text into chunks of 300 to 500 tokens provides the best balance. This size captures enough context for the model to understand the subject without diluting the specific meaning, which degrades the cosine similarity score.
Why do AI search agents timeout on dynamic websites?
AI crawlers allocate very little computational time per URL. If a website relies on heavy client-side JavaScript to render its primary text, the crawler drops the connection rather than spending resources rendering the page, resulting in indexing failures.
Does generative imagery affect local search performance?
It severely damages performance if generated synchronously during the page load, as the processing time ruins the Time to First Byte (TTFB). Generative images must be created asynchronously, compressed, and served statically via a CDN to maintain search performance.