How to Architect Enterprise Solutions with Google Cloud AI
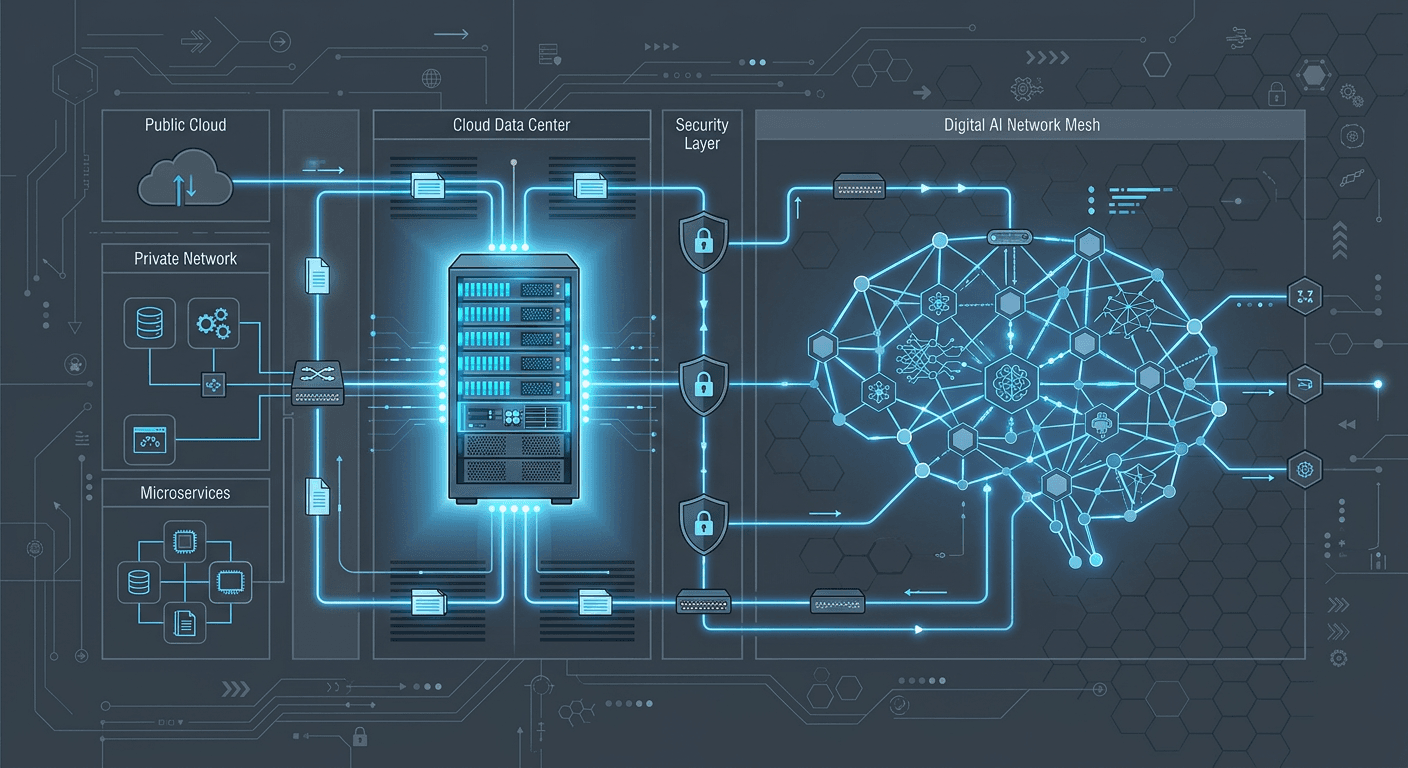
Engineering teams often treat Google Cloud AI as a simple REST endpoint they can query whenever a user interacts with an application, only to watch latency spike to 4000ms and inference costs consume their entire cloud budget within a week. Integrating machine learning into a business process is a deep infrastructure challenge, not just a software development task. When you move beyond simple API wrappers, you have to architect for aggressive rate limits, massive token context windows, and asynchronous data pipelines. If a solution is not properly segmented across staging and deployment environments, a single malformed payload can crash your entire processing queue. This guide breaks down the actual mechanics of moving machine learning models from prototype environments into reliable, secure, and low-latency production workflows you can trust at scale.
Quick Summary
Deploying enterprise architecture with Google's machine learning infrastructure requires strict separation between prototyping tools and production endpoints. Building reliable workflows involves managing memory payloads, enforcing identity boundaries, and handling rate limits before traffic scales.
- Migrate early from testing environments to dedicated production endpoints.
- Pass large image payloads via cloud storage rather than direct HTTP requests.
- Enforce idle shutdown schedules on all notebook instances to control billing.
- Source infrastructure templates to standardize your deployment configurations.
Table of Contents
- 1. Map compute resources in Google AI Studio
- 2. Process unstructured images with Google Vision API
- 3. Manage environments in the Google AI lab
- 4. Validate architectures with a Google developers group
- Why deployments fail under production loads
- FAQ
1. Map compute resources in Google AI Studio
Where prototyping tools fail in production
Behind the scenes, Google AI Studio wraps standard inference requests with an experimentation-focused authentication layer. Teams frequently build their initial prompts here. The graphical interface handles tokenization, temperature adjustments, and system instructions visually. This setup is excellent for dialing in the exact tone and behavior of a conversational agent. It also works well for generating baseline code. Still, wiring this directly into a live application is dangerous. Older documentation occasionally refers to this ecosystem as Google Studio AI. The underlying mechanics remain the same. It operates as a developer sandbox, not an enterprise hosting provider.
The most common failure mode here is engineers exporting the API key directly from the studio environment and embedding it into a serverless function. When traffic spikes, the experimentation quota is immediately exhausted, resulting in HTTP 429 Quota Exceeded errors. Furthermore, prototype environments rarely enforce the strict data residency requirements needed for enterprise compliance.
To fix this, you must transition the workload to Vertex AI. This migration involves creating a dedicated service account, applying the Vertex AI User role, and authenticating via OAuth 2.0 bearer tokens rather than passing a static string. You must also explicitly select a regional location, such as europe-west1, to ensure that data residency requirements are met. You can act on this today by auditing your environment variables: search for any key beginning with the standard studio prefix. If you find one in a production configuration, rotate it immediately and transition to standard identity and access management bindings.
2. Process unstructured images with Google Vision API
Why direct uploads block the event loop
When building optical character recognition (OCR) or object detection pipelines, the Google Vision API provides a fully managed endpoint that avoids the overhead of training custom models. The API accepts image payloads in two distinct ways: as a base64 encoded string embedded directly in the JSON request, or as a reference to a Google Cloud Storage (GCS) URI.
The primary mistake developers make is passing base64 strings for high-resolution images over standard synchronous REST calls. Base64 encoding inflates the physical file size by converting binary data into text. If your application relies on a single-threaded environment like Node.js, parsing and encoding a large image in memory will block the event loop. This causes health checks to fail and prompts the load balancer to terminate the container entirely.
Practical rule: Always decouple file uploads from inference requests by writing media to a cloud storage bucket first, and pass only the resulting URI to the machine learning endpoint.
This architectural shift moves the heavy lifting out of your application memory and into the cloud provider's internal network. When you pass a GCS URI, the API reads the file directly from storage. For bulk processing, you must switch from synchronous requests to the asynchronous batch annotate method, which writes the JSON results directly back to a separate output bucket. You can act on this today by checking your application logs for memory spike warnings or HTTP 413 Payload Too Large errors. If your ingress controllers are dropping packets during image processing, you are encoding media in memory instead of using cloud storage references.
3. Manage environments in the Google AI lab
How idle compute instances drain budgets
Data science teams require isolated environments to test data manipulation and model training scripts. This workflow is typically managed through Vertex AI Workbench, heavily utilized as a managed Google AI lab. When a user requests a new notebook, the platform dynamically provisions a Compute Engine virtual machine, mounts a persistent disk for data storage, and attaches a default service account to handle API requests.
The most frequent mistake in this phase is treating these cloud instances like standard desktop applications. Engineers will often train a model, close their browser tab, and assume the session is terminated. Because the underlying virtual machine remains active, the cloud provider continues to bill for the attached GPU and CPU resources at an hourly rate. Over a single weekend, an idle cluster can consume thousands of dollars in unnecessary compute costs.
To prevent this, you must apply strict lifecycle policies to the underlying infrastructure rather than relying on human behavior. You can act on this immediately by navigating to your cloud console and configuring an idle shutdown schedule for all lab instances. Set the threshold to 120 minutes of inactivity. Additionally, instead of relying on default libraries, teams should build custom Docker images containing the exact versions of the frameworks they need. Relying on package installation commands run manually inside a notebook cell guarantees that the deployment will eventually fail due to version drift when moving to a production pipeline.
4. Validate architectures with a Google developers group
Why copied templates expose cloud resources
Infrastructure-as-code (IaC) templates provide an immediate baseline architecture. Building cloud infrastructure from scratch is rarely necessary when deploying standard machine learning endpoints. The most effective approach is sourcing these templates from community repositories or a verified Google developers group. These communities maintain Terraform modules and Deployment Manager scripts. They define the exact networking rules and identity bindings. The files also specify the resource limits required to run models safely.
The critical failure occurs when teams clone these repositories. They apply them to their production environments without auditing the underlying IAM roles. A template built for a local meetup demonstration is explicitly designed to bypass security hurdles. This gets the model running quickly. It will often grant the 'Editor' role to the runtime service account. This effectively gives the machine learning model the ability to delete databases. It can also provision new infrastructure unprompted. For agencies relying on precise infrastructure to scale operations, managing these security boundaries is paramount. This is exactly why specialized tools for AI-driven SEO for tech companies automate compliance and data visibility without requiring manual Terraform interventions.
If you are building your own pipelines, you must review the code manually. You can check your current exposure today by running a policy analyzer against your active Terraform state files. Look specifically for any excessive bindings attached to compute service accounts and replace them with least-privilege roles.
Why deployments fail under production loads
Transitioning from a working prototype to a live enterprise application reveals entirely new classes of infrastructure errors. These failures often masquerade as simple bugs, but they require architectural fixes rather than code-level patches.
Quota exhaustion masking as network timeouts When traffic increases rapidly, inference requests will begin to fail with HTTP 429 errors. The standard assumption is that the application has exceeded its requests-per-minute quota. In reality, large conversational payloads almost always hit the tokens-per-minute limit first. Sending massive context windows on every turn of a conversation consumes tokens exponentially. The fix: Implement a sliding window for context caching. Truncate conversation history to the most recent three interactions before sending the payload, and request a quota increase based on calculated token usage rather than total user count.
Serverless cold starts degrading user experience Your API endpoints might normally respond in 500 milliseconds, but sporadically take upwards of 8000 milliseconds to return a result. This inconsistency happens when the serverless container handling the inference request scales down to zero during idle periods. When a new request arrives, the cloud provider must provision a new container, download the runtime environment, and establish a fresh network connection. The fix: Configure a minimum instance count for your deployment environment. Keeping at least one node permanently warm ensures that baseline traffic never experiences the startup latency penalty.
Cross-contamination of identity roles Security command centers frequently flag machine learning applications for excessive API access. This symptom appears when engineering teams use a single, project-wide service account for both frontend web applications and backend model training. If the frontend is compromised, the attacker gains the ability to manipulate the training data stored in secured buckets. The fix: Split your identities immediately. Create one heavily restricted service account strictly for model invocation, and a separate, isolated account solely for accessing training data.
Runaway inference costs without user growth Your monthly cloud bill may spike aggressively even if active user counts remain flat. This occurs when applications run unbounded retries on failed inference requests without exponential backoff. If the API rate-limits a request, a poorly configured frontend will instantly fire another request, creating a localized denial-of-service attack that generates massive bandwidth costs. The fix: Implement exponential backoff algorithms with a hard cap on retry attempts. Ensure that client applications gracefully degrade or display an error message after three failed attempts rather than looping infinitely.
FAQ
How do you secure proprietary data passed to these APIs? Enterprise endpoints are designed with strict data residency and isolation protocols. Unlike public consumer chatbots, data sent to dedicated cloud machine learning endpoints is not logged or used to train foundation models. You secure the transit by routing traffic through private VPC networks rather than the public internet.
What differentiates an experimental endpoint from a production environment? Experimental environments prioritize rapid iteration and visual debugging but offer no service-level agreements regarding uptime or latency. Production environments require programmatic authentication via service accounts, enforce strict IAM boundaries, and guarantee uptime through financial SLAs.
Can these architectures operate in a multi-cloud configuration? Yes, but the integration points change. While the core models are hosted on specific cloud infrastructure, you can invoke them from external clouds by federating identities using Workload Identity Federation. This allows external servers to request short-lived access tokens without storing permanent credentials.
How should we monitor model degradation in production? You must log the confidence scores returned by the API alongside the actual user input. By analyzing the drift in confidence scores over time, you can detect when the model is encountering data patterns it was not exposed to during initial tuning, allowing you to trigger retraining pipelines.
Why does object detection fail on high-resolution photography? Managed computer vision APIs apply automated downsampling algorithms to images that exceed their maximum pixel dimensions. If critical details are compressed out of the image during this process, the model will fail to detect them. You must crop or tile high-resolution images manually before passing them to the pipeline.