How to Optimize IT Infrastructure with Business Process Automation
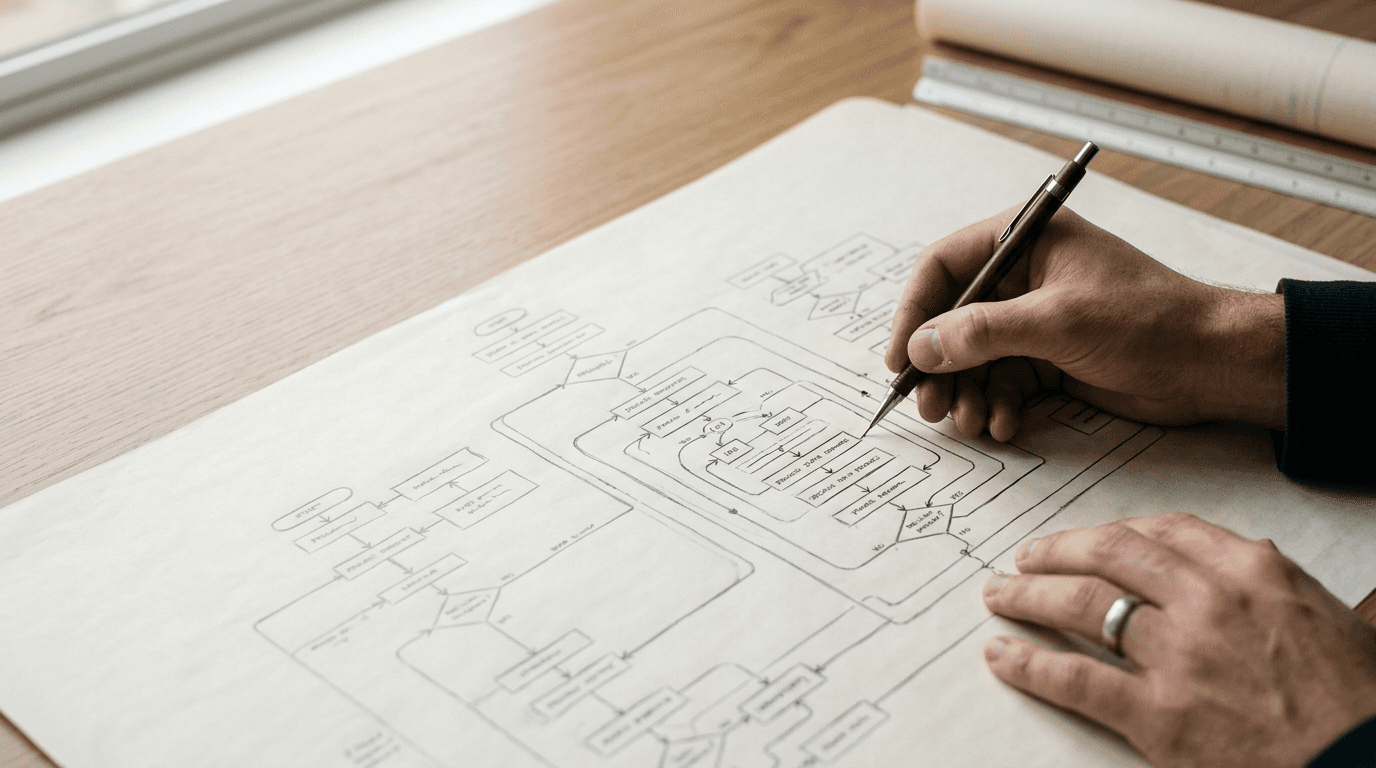
Most IT directors treat business process automation as a software procurement exercise, assuming that buying a hyperautomation suite will naturally fix a slow, disjointed operational pipeline. In reality, wrapping a new orchestration engine around a broken, manual handoff simply executes the same flawed sequence at a higher frequency, generating unmanageable technical debt and compounding latency across the entire network. To genuinely optimize internal workflows and operational infrastructure, you must rebuild the logic from the ground up, mapping the exact state changes of every data packet before a single line of automation script is deployed.
Quick Summary
Business process automation requires mapping state transitions, reengineering legacy logic, and deploying robust architecture to execute workflows without human intervention. Skipping the foundational modeling phases results in brittle deployments that fail under scale.
- Map existing workflows precisely before attempting to automate them.
- Align automated processes with the broader architectural standards of the organization.
- Strip out redundant approval loops and batch processes during the reengineering phase.
- Design for failure by integrating resilient failover mechanisms directly into the logic.
Table of Contents
- 1. Define the baseline with business process modeling
- 2. Align workflows with business enterprise architecture
- 3. Execute business processing reengineering
- 4. Integrate business continuity management
- 5. Deploy infrastructure for automated scaling
- Common Pitfalls & Troubleshooting
- FAQ
- Recommended Reads
1. Define the baseline with business process modeling
The absolute prerequisite to automating any operational workflow is establishing a granular, mathematically sound representation of how the work currently happens. This is the domain of business process modeling, where you translate human habits, undocumented workarounds, and implicit approvals into explicit, diagrammatic logic using standards like BPMN 2.0. You cannot automate a process you cannot accurately describe. The modeling phase forces the operations team to document every input, output, system dependency, and decision gate. It requires mapping the data payload at each node, defining exactly what information is required to transition a task from a pending state to a completed state.

The mechanics involve shadowing the actual practitioners. Inspect legacy API logs. Map the exact sequence of events. You must identify the "happy path" where everything works perfectly. But more importantly, you must document every exception, error-handling loop, and manual intervention required when the primary logic fails. A workflow that looks linear on a whiteboard often contains hidden cyclic dependencies when examined at the database level. For instance, a local Italian startup aiming to optimize its AI content production pipeline must map exactly how a drafted article passes through compliance checks, API limits, and publishing queues. Only then can they script the transitions.
The most common mistake at this stage is modeling the process as management believes it operates, rather than how the floor actually executes it. When you build automation based on an idealized flowchart, the resulting system immediately breaks upon encountering the first real-world exception that the frontline workers normally handle via Slack or an undocumented spreadsheet. The automation stalls, throwing unhandled exceptions, and requires manual rescue, defeating the purpose of the deployment.
Practical rule: Always model the exceptions and error states first; the "happy path" will dictate the primary logic, but the error handling dictates whether the automation survives in production.
2. Align workflows with business enterprise architecture
Once the baseline is mapped, the proposed automation must be validated against the organization's business enterprise architecture. This ensures that the automated workflow respects the structural boundaries, security policies, and data governance frameworks established by the company. Automation does not exist in a vacuum; it consumes compute resources, interacts with identity and access management (IAM) protocols, and moves data across network segments. If an automated process violates a data residency requirement or bypasses a mandatory security gateway, it introduces massive compliance risks, particularly in heavily regulated environments.
The mechanics of this alignment require cross-referencing the modeled workflow against the architectural blueprints. You must determine which systems of record the process will interact with, how it will authenticate (e.g., using service accounts with least-privilege access rather than hardcoded credentials), and whether the underlying network topology can support the anticipated spike in API calls. If the architecture mandates that all external data ingestion pass through a specific DMZ or web application firewall, the automation script must be routed accordingly. For companies relying on high-speed local infrastructure with strict SOC2 Type II compliance requirements, every automated data transfer must be logged, encrypted, and verifiable within that architecture.
The critical error here is treating automation as an overlay rather than an integrated component. Teams often deploy lightweight automation scripts using shadow IT tools or third-party cloud connectors that are not sanctioned by the enterprise architecture board. These rogue automations create insecure data conduits, bypass logging requirements, and inevitably fail when the IT department updates a firewall rule or rotates a security certificate, causing the "invisible" workflow to silently break and corrupt downstream data.
3. Execute business processing reengineering
Taking a flawed, manual process and automating it directly is a recipe for operational disaster. Before writing code, you must execute business processing reengineering, which involves fundamentally redesigning the workflow to eliminate unnecessary steps, remove obsolete approvals, and optimize for machine execution rather than human constraints. Manual processes are typically designed around batch processing and human review cycles; automated processes should be designed for real-time, event-driven streaming.
Reengineering requires stripping the process down to its core objective. If a legacy workflow requires a manager to manually approve a data transfer because the old system was prone to errors, and the new automated system uses strict schema validation to guarantee data integrity, that approval step must be deleted. It is not enough to automate the approval email; the requirement itself must be excised. You must redesign the logic to utilize parallel processing wherever possible, allowing independent tasks to execute simultaneously rather than forcing them into an artificial sequential queue. This drastically reduces the total execution time and maximizes resource utilization.
The failure mode in this step is "paving the cow path" - replicating physical or manual limitations in the digital realm. A classic example is maintaining a daily batch job for data synchronization simply because a human used to run a report at 5 PM, rather than switching to an event-driven web-hook model that synchronizes the data instantaneously. Paving the cow path guarantees that the business realizes only a fraction of the potential speed and efficiency gains, paying for automation while retaining the bottlenecks of a manual era.
4. Integrate business continuity management
Automated systems run faster and process larger volumes of data than human operators, meaning that when they fail, they fail at scale. Therefore, business continuity management must be woven directly into the fabric of the automated infrastructure. This is not about writing a disaster recovery document; it is about engineering resilient logic that can detect failures, automatically failover to secondary systems, and alert human operators without corrupting the dataset or dropping transactions.
Mechanically, this involves implementing robust idempotency in your automation scripts. An idempotent operation is one that can be applied multiple times without changing the result beyond the initial application. If a network timeout causes an automated process to retry a database insertion, idempotency ensures that the record is not duplicated. You must also establish clear circuit breakers - mechanisms that temporarily halt the automation if a downstream system (like an external API or a legacy database) begins returning error rates above a certain threshold, preventing the automation from hammering a struggling system into total collapse.
The mistake practitioners make is assuming the infrastructure will always be available. They write scripts that assume a 200 OK response from every API call and fail spectacularly when a third-party service experiences a micro-outage. Without engineered continuity, a temporary network blip causes the automation to crash midway through a transaction, leaving the data in an inconsistent, locked state that requires hours of manual database surgery to resolve.
5. Deploy infrastructure for automated scaling
The final step is deploying the optimized, reengineered workflow onto an infrastructure capable of handling the automated load. Automation fundamentally shifts the operational bottleneck from human availability to compute and network capacity. A process that used to generate ten database queries an hour might now generate ten thousand per minute, requiring a resilient, scalable backend to prevent system degradation.
The deployment mechanics require configuring dynamic scaling policies within your cloud or edge computing environment. The infrastructure must be able to spin up additional containerized workers or serverless functions in response to queue depth or CPU utilization. For time-sensitive tasks where latency is critical - such as real-time SEO adjustments or automated threat mitigation - you must provision infrastructure that guarantees minimal delay, ensuring the network routing does not introduce artificial drag on the automated workflows. Proper telemetry and observability tools must be deployed alongside the automation to track execution times, error rates, and resource consumption in real-time.
The fatal error at deployment is severely under-provisioning the database connection pool. As the automation scales out and spins up hundreds of concurrent workers, they quickly exhaust the available connections to the primary database. The application layer scales beautifully, but the database refuses new connections, resulting in a catastrophic bottleneck where the automation engine queues up thousands of tasks that cannot be committed to disk.
Common Pitfalls & Troubleshooting
When automated infrastructure fails, the symptoms often look identical from the outside: the process stalls, data stops moving, and error logs fill up. Diagnosing the exact root cause is critical to restoring functionality without corrupting the operational state.
Symptom: The automation frequently stalls entirely, with jobs stuck in a "processing" state indefinitely without throwing a formal error. Diagnosis: This is typically a cyclic dependency or a deadlock within the database layer. Two automated processes are waiting on each other to release a lock on a specific table or record. Fix: You must analyze the database transaction logs to identify the competing queries. The fix involves rewriting the process logic to acquire locks in a strict, predictable order, or breaking the transaction down into smaller, atomic operations that do not require holding extensive locks.
Symptom: Downstream systems are overwhelmed, and external APIs are returning HTTP 429 (Too Many Requests) errors, causing the automation to fail. Diagnosis: The automation is executing faster than the target systems can ingest the data, lacking proper pacing or rate limiting. Fix: Implement an event queue (like Kafka or RabbitMQ) between the automation engine and the downstream system. Configure the automation to publish messages to the queue, and use rate-limited consumer workers to pull the data from the queue and push it to the API at a compliant speed.
Symptom: Automated workflows are completing successfully according to the logs, but the output data is consistently malformed or missing key fields. Diagnosis: The upstream data schema has changed without notifying the automation layer. The process is executing perfectly on invalid input. Fix: Implement strict schema validation at the very beginning of the automated workflow. If the incoming payload does not match the expected structure, the process must immediately halt and route the payload to a dead-letter queue for manual review, rather than processing garbage data.
FAQ
How do you determine which processes are ready for automation?
Processes that are highly structured, rely on structured data, and have minimal requirements for subjective human judgment are the best candidates. If a process requires a human to "read the room" or interpret vague text, it requires reengineering before automation.
Why does automation sometimes increase the operational cost initially?
Because you are paying for both the legacy manual execution and the development, testing, and deployment of the automated infrastructure simultaneously. The ROI is realized only after the automated system reaches a stable production state and the manual resources are reallocated.
What role does security play in operational automation?
Security must be embedded in the workflow design. Automated service accounts must be governed by least-privilege access, all API keys must be stored in secure vaults (not hardcoded), and every automated action must generate an immutable audit log.
Can you fully automate an operational pipeline without reengineering it?
Technically yes, but it is highly inadvisable. Automating a broken or inefficient manual process simply executes a bad design faster, scaling the inefficiencies and creating brittle infrastructure that is prone to constant failure.