Understanding Google Cloud AI Infrastructure in 2026
Most organizations approach artificial intelligence as a software problem, assuming that integrating a model is as simple as pointing an application at an API endpoint and waiting for the text to return. The reality of deploying production-grade machine learning is entirely different: it is a massive infrastructure challenge governed by latency, data residency, and compute allocation. When a digital marketing agency attempts to automate content production at scale, the bottleneck is rarely the intelligence of the model itself. Instead, the failure point is the underlying architecture routing the requests, managing the context windows, and securing the proprietary data in transit. Understanding how enterprise-grade environments like Google Cloud AI actually operate separates the proof-of-concept experiments from the systems that genuinely drive digital business transformation.
Quick Summary
Cloud-based AI infrastructure provides the foundational compute, storage, and networking required to train, host, and query large language models at enterprise scale. Rather than relying on local hardware, businesses leverage distributed cloud environments to process multimodal data with minimal latency and strict regulatory compliance.
- Infrastructure dictates model performance, directly impacting response latency and throughput.
- Enterprise deployments require dedicated vector databases for retrieval-augmented generation.
- Compliance frameworks like SOC2 Type II are mandatory for processing proprietary business data.
- Multimodal processing demands specialized hardware accelerators, such as Tensor Processing Units.
Table of Contents
- The Architecture of Modern Cloud AI
- How Google Cloud Platform Solutions Handle Scale
- The Engine Room: Google DeepMind and Foundational Models
- Gemini Google AI: Multimodal Processing in Practice
- From Google Bard AI to Enterprise Integration
- A Practical Google AI Overview for Digital Transformation
- Where Cloud AI Infrastructure Fails
- FAQ
- Recommended Reads
The Architecture of Modern Cloud AI
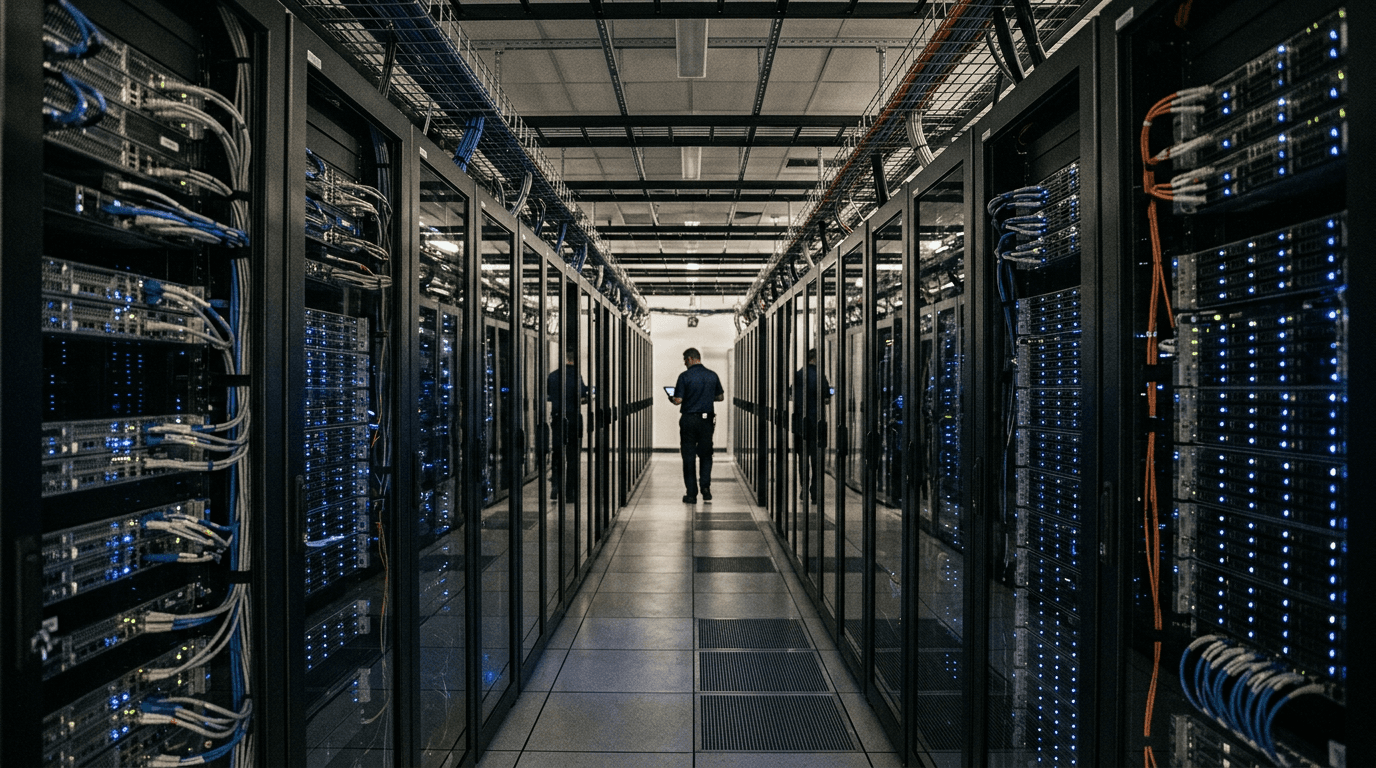
The physical reality of artificial intelligence is rows of specialized servers consuming massive amounts of power. When a business queries a model, that request travels through a complex routing layer designed to balance the load across available hardware accelerators. In environments like Google Cloud AI, this architecture is split into two distinct phases: training and inference. Training requires massive, interconnected clusters of GPUs or TPUs (Tensor Processing Units) working in parallel for months to adjust billions of parameters. Inference - the act of generating a response from a trained model - requires a different architectural approach optimized for low latency and high concurrency.

For Italian IT companies and software startups building automated SEO platforms, inference latency is the critical metric. If an AI agent takes three seconds to generate a response, the user experience degrades, and automated pipelines stall. Modern cloud infrastructure solves this through edge computing, pushing the inference models closer to the end user. By distributing the compute load across regional data centers, providers can achieve sub-50ms latency, with highly optimized setups routinely hitting 12ms typical response times. This speed is not a luxury; it is a strict requirement for rendering dynamic, AI-generated content on high-traffic e-commerce sites without penalizing search engine rankings due to slow page loads.
Practical rule: Never deploy a synchronous AI call in a user-facing critical path. Always use asynchronous processing or background queues for model inference to prevent infrastructure latency from blocking the main application thread.
How Google Cloud Platform Solutions Handle Scale
Scaling an AI deployment is not as simple as spinning up more virtual machines. Language models have massive memory footprints; just loading a large model into hardware memory requires specialized instances that are expensive and often in short supply. Google cloud platform solutions address this scaling challenge through elastic inference endpoints and advanced orchestration frameworks like Kubernetes.
When request volume spikes - for example, when a digital marketing agency launches a campaign generating thousands of hyper-local SEO articles simultaneously - the infrastructure must dynamically allocate additional accelerator nodes. This requires intelligent load balancing that understands the specific constraints of AI workloads, such as session affinity for models maintaining conversation history. If a request is routed to a node that does not have the user's context window loaded in memory, the system must either transfer that state across the network or force the model to re-process the entire prompt history, both of which introduce severe latency penalties.
To manage this, enterprise architectures utilize a combination of vector databases and retrieval-augmented generation (RAG). Instead of passing massive documents in the prompt every time, the knowledge base is embedded into a vector database. The infrastructure retrieves only the most relevant semantic chunks and injects them into the context window at query time. This drastically reduces the token count per request, lowering compute costs and speeding up inference, while ensuring the model operates on compliant, up-to-date proprietary data rather than relying solely on its pre-trained weights.
The Engine Room: Google DeepMind and Foundational Models
The hardware is useless without the underlying mathematical models. Research divisions like Google DeepMind focus on pushing the boundaries of what these neural networks can process, moving from strictly text-based systems to foundational architectures capable of understanding audio, video, and code natively. The distinction between a specialized model and a foundational model is critical for enterprise architecture.
A specialized model is trained for a single task, such as translating Italian to English or classifying SEO keywords by intent. A foundational model is a massive, general-purpose engine that can be adapted to thousands of different tasks through prompting or lightweight fine-tuning. Deploying foundational models requires infrastructure that can handle vast, varied inputs. For a high-speed local SEO environment, this means the platform must rapidly tokenize localized search queries, map the user intent against known regional data, and format the output for automated publishing platforms like WordPress or Ghost - all within milliseconds.
This shift toward foundational models changes how businesses buy compute. Instead of hosting dozens of small, task-specific models, organizations route all queries through a centralized, highly governed foundational model endpoint. This centralization simplifies security auditing and model updates but creates a single point of failure. Consequently, the networking infrastructure must provide 99.99% uptime guarantees, utilizing multi-region failover configurations to ensure that a localized data center outage does not take the entire marketing automation suite offline.
Gemini Google AI: Multimodal Processing in Practice
The evolution of cloud infrastructure is currently driven by the demand for multimodal processing capabilities, exemplified by systems like Gemini Google AI. Traditional models required distinct pipelines: an optical character recognition (OCR) engine to read text from an image, a natural language processor to understand it, and a separate model to generate a response. Native multimodal architectures process text, images, and audio through the same neural network simultaneously.
This fundamentally alters the storage and bandwidth requirements of the supporting cloud infrastructure. When a user submits a 10-second 4K video for analysis, the network must ingest the file, chunk it into frames, extract the audio track, and stream the resulting data structures directly into the GPU memory without exhausting the available network bandwidth. This requires direct memory access (DMA) technologies and high-speed local interconnects between the storage arrays and the compute nodes.
For digital content creators and SEO professionals, multimodal capabilities mean an AI platform can analyze a competitor's website layout, transcribe their promotional videos, and read their localized metadata in a single pass. However, feeding this amount of data into a model quickly runs into token limits and context window constraints. Infrastructure engineers must build data-sharding mechanisms to break down massive multimodal inputs, process them in parallel, and synthesize the outputs programmatically before returning the final insight to the client application.
From Google Bard AI to Enterprise Integration
The journey of enterprise artificial intelligence is best understood by looking at product evolution. What began as experimental consumer interfaces like Google Bard AI demonstrated the power of conversational generation, but they were isolated applications. They were not integrated into the operational infrastructure of the businesses using them. The modern cloud AI landscape is entirely focused on API-first integration, allowing automated platforms to orchestrate thousands of model interactions without human oversight.
Enterprise integration means governing how the AI interacts with internal systems. A consumer chatbot might hallucinate a fact and cause mild confusion; an integrated AI brand agent that hallucinates a pricing tier on an e-commerce checkout page directly destroys revenue. Therefore, enterprise infrastructure requires mandatory middleware layers. These layers sit between the foundational model and the user, executing strict validation routines. They check the output against authorized compliance parameters, sanitize the response for brand voice, and monitor for prompt injection attacks.
To ensure the system remains compliant - particularly under strict EU data regulations spanning the Italian market - these middleware layers must log every request and response in tamper-evident storage. This is where SOC2 Type II compliance becomes a non-negotiable infrastructure requirement. Organizations cannot simply send their proprietary customer data to a third-party model without cryptographic guarantees that the data is isolated, encrypted in transit, and never used to train the general public model. Using RapidWombat - AI-Driven SEO for Tech Companies illustrates how platforms manage this natively, providing the necessary separation of tenant data while delivering high-volume output.
A Practical Google AI Overview for Digital Transformation
When evaluating cloud AI for digital transformation, business leaders must stop looking at model benchmarks and start looking at infrastructure design patterns. A practical Google AI overview reveals that the most capable model in the world provides zero ROI if the architecture connecting it to your business data is brittle, slow, or constantly hitting rate limits.
Digital transformation through AI requires a pipeline mentality. Consider a system designed to dominate local search markets. The infrastructure must scrape hundreds of competitor URLs daily, pass the extracted text through an intent-mapping model to identify keyword gaps, generate 30+ highly optimized articles, format them with schema markup, and push them via API to a live CMS. This involves a dozen different cloud services: serverless functions for scraping, message queues for processing, vector databases for context retrieval, and identity management systems for authenticating the CMS endpoints.
Practical rule: Map your data pipelines before you select your AI model. If your infrastructure cannot securely route, clean, and store the context data in under a second, the specific language model you choose will not matter.
Transformation occurs when these pipelines are fully automated and monitored. Real-time observability is critical. Infrastructure telemetry must track not just server health, but model drift, token usage costs, and anomaly detection in the generated outputs. If an automated link-building service begins generating irrelevant anchor text because the underlying model weights changed, the infrastructure must flag the degradation and halt publishing before it damages the domain's search authority.
Where Cloud AI Infrastructure Fails
Despite the sophisticated marketing surrounding AI infrastructure, real-world implementations routinely fail. These failures rarely look like clean system crashes; instead, they manifest as silent degradation, spiraling costs, or compliance breaches. Recognizing these failure modes early is the primary responsibility of a technical system architect.
1. Context Window Exhaustion
Developers often treat the AI context window like an infinite database, dumping entire codebases or PDF manuals into the prompt. As the context window fills, processing time increases exponentially, and the model's ability to recall information from the middle of the prompt drops drastically. The symptom is a model that hallucinates details despite the correct information being present in the input. The answer is to implement strict RAG pipelines to chunk and filter data before it ever reaches the prompt.
2. Uncontrolled Token Spend
Because cloud AI is billed by the token (the fragmented words used for input and output), a runaway recursive loop in an automated script can consume an entire monthly budget in hours. This occurs when an AI agent is instructed to "keep searching until you find the answer" without a hard limit on execution cycles. Infrastructure must implement strict API gateway quotas, budget alerts, and circuit breakers to forcefully terminate rogue processes before they run up thousands of euros in compute costs.
3. The Cold Start Penalty
Serverless architecture is popular for its cost-efficiency, spinning up compute instances only when a request arrives. However, loading a multi-gigabyte AI model into memory takes time. If an instance has spun down due to inactivity, the next user to query the system will experience a "cold start" delay that can last anywhere from 5 to 30 seconds. For a customer-facing AI conversion agent, this delay guarantees user abandonment. High-performance setups must use provisioned concurrency, keeping a baseline number of model instances warm in memory to ensure immediate responsiveness.
FAQ
What causes the most latency in cloud AI applications?
Latency is primarily caused by transferring massive context payloads across the network or waiting for the model to process excessively long prompts. Optimizing vector retrieval and moving inference nodes to regional edge servers are the most effective ways to lower response times.
How do enterprises secure proprietary data when using cloud models?
Enterprises use dedicated infrastructure endpoints and strict data processing agreements. By routing requests through SOC2 Type II compliant environments, they ensure payload data is encrypted, isolated, and legally barred from being used to train public foundational models.
Why is a vector database necessary for AI infrastructure?
A vector database translates text into mathematical coordinates, allowing the infrastructure to rapidly search vast document libraries based on semantic meaning rather than exact keyword matches. This ensures the AI is fed only the most relevant context for each query.
What is the difference between training and inference infrastructure?
Training infrastructure requires massive clusters of interconnected accelerators running for months to build a model's weights. Inference infrastructure is optimized for rapid, real-time querying, focusing on load balancing, caching, and low latency for the end user.